Capability: the layers and the evidence in detail
The benchmark table, the seven layers in full, the ceiling and the floor, and the scope notes behind Part 1.
This page is the reference for Part 1, Capability is a system property. Part 1 makes the argument in about 25 minutes. This page holds the detail that moved out of it, unchanged. Read it section by section, as you need it.
A section named here that is not on this page is in Part 1. Lever, layer and figure numbers in the text follow this page. Figures were checked on the dates given in Part 1.
Measurement discipline
Which benchmark measures what
The benchmarks that pass the lifecycle filter, grouped by what each measures:
| # | Benchmark | What it measures | Status | Role |
|---|---|---|---|---|
| A. Capability ceiling on economically valuable knowledge work | ||||
| A1 | Epoch Capabilities Index (ECI) (Epoch AI, Oct 2025; Ho et al., arXiv 2512.00193) | Composite "general capability" scale stitching 40+ benchmarks | Live, updated continuously; resists single-benchmark saturation by design | Composite trend signal. A 5-point ECI gain corresponds to a doubling of the METR time horizon at launch calibration. |
| A2 | GDPval (Patwardhan et al., arXiv 2510.04374) | Single-deliverable parity with human experts across 44 occupations | Non-saturated by design (preference share) | The canonical ceiling number. 47.6% at launch (Opus 4.1, 2025); 84.9% by April 2026 (GPT-5.5, vendor-reported) |
| A3 | GDPval-AA (Artificial Analysis) | Same target, run through a standard open harness ("Stirrup") | Live | Third-party reimplementation; Claude Opus 5.5 leads as of October 2026 |
| A4 | Humanity's Last Exam (CAIS + Scale, arXiv 2501.14249) | Closed-form expert knowledge across math, sciences, humanities | Climbing fast, non-saturated | Frontier knowledge ceiling. Use sparingly. Knowledge is closer to closed-form reasoning than to economic work. |
| B. Long-horizon / autonomous capability | ||||
| B1 | METR Task-Completion Time Horizons (Time Horizon 1.1, Jan 2026) | Length of task at a given reliability threshold | Tracker no longer updated since September 2026; newer models exceed the suite | The illustration of how the reliability threshold changes the headline number by a factor of ten |
| B2 | Remote Labor Index (Mazeika et al., arXiv 2510.26787) | End-to-end autonomous completion of real freelance projects | Non-saturated; best agent 41.3% (Fable 5.2, Nov 2026, run by Scale AI), up from 21.25% (Opus 5.5, Scale leaderboard, Oct 2026), 15.8% (CAIS, Jul 2026) and 2.5% (Oct 2025 release) | The autonomous end of the ceiling: a whole project with no person in the loop. Pair with GDPval to see what autonomy costs. Official leaderboard is scored by trained human experts |
| C. Coding capability (current generation, non-saturated) | ||||
| C1 | SWE-bench Pro (Scale / SEAL) | Real GitHub issues across larger codebases | Non-saturated. Three distinct measurement conditions: vendor-reported ~90% (Opus 5.5, Sep 2026), standardised public ~59% (Aug 2026; Scale's V2 board not yet independently checked), private commercial ~47% | Successor to Verified after OpenAI's contamination audit. Always state which one you are quoting |
| C2 | SWE-bench Live (Microsoft, arXiv 2505.23419) | Same target, on issues never seen during training | Non-saturated by design | 50 verified issues added monthly |
| C3 | SWE-Rebench | Continuously-refreshed SWE-bench analogue | Non-saturated by design | Pairs with Live for reading trends across snapshots |
| C4 | Terminal-Bench 4.0 (tbench.ai, 26 Aug 2026; Merrill et al., arXiv 2601.11868) | Long agentic tasks in a terminal; 66 tasks, median about four hours of expert work, eight-hour agent budget | Non-saturated. Official board top 64.8%; independent minimal-harness runs 63-65%. Rated "Flawed" by Epoch AI (scoring defects in 30 of 66 tasks) | The main same-model harness comparison here. Not comparable with 2.x scores. Prefer the median of independent boards to any single number |
| D. Agent capability, tool use, and sub-skills | ||||
| D1 | HAL (Kapoor et al., arXiv 2510.11977) | Cost-aware agent capability across nine benchmarks in the paper; the live leaderboard lists more | Live; main leaderboard paused for Reliability Dashboard | The recommended internal-eval pattern |
| D2 | GAIA (via HAL) | Multi-step real-world reasoning | Non-saturated; on HAL the same model scores up to 44 points apart in two different scaffolds | A concrete instance of tool-augmented small models outperforming unaugmented large ones |
| D3 | τ-bench / τ²-bench (Sierra, arXiv 2406.12045 / 2506.07982) | Customer-facing agent capability with explicit reliability separation | Non-saturated; passk drops sharply from pass@1 | Operationalises the rule against folding reliability into capability |
| D4 | BFCL v4 (UC Berkeley / Gorilla) | Function calling, web search, memory, multi-turn, format sensitivity | v3 saturating; v4 non-saturated | Tool-use capability sub-dimension |
| D5 | NoLiMa (Modarressi et al., ICML 2025, arXiv 2502.05167) | Long-context functional capability with literal lexical overlap removed | Non-saturated; 11 of 13 models below 50% of short-context baseline at 32K | The empirical case that adding context fails to add capability |
| D6 | RULER / ONERULER (NVIDIA) | Long-context capability across task types and languages | Non-saturated within claimed limits | Companion to NoLiMa |
| D7 | MTEB / MMTEB (HuggingFace) | Retrieval and embedding capability | Live; competitive open-weights | How you choose a retrieval primitive |
| D8 | OSWorld-Verified / OSWorld 2.0 (XLANG Lab, HKU) | Computer-use agent capability in real desktops | Verified saturated (~85-86%, human baseline 72.4%). 2.0 (108 long-horizon tasks, Jun 2026) non-saturated: 20.6% at release (Opus 4.8); 44.3% top score on a revised task set on the Snorkel-hosted board (Claude Opus 5, which scored 31.4% on the August release). OSWorld 2.1, offline set of 82 tasks: Fable 5.2 earns 89.3% partial credit and passes 54.6% in full (vendor-reported, Nov 2026) | A clean saturation-versus-frontier pair. Non-comparable benchmarks despite the shared name |
| E. The realisation gap | ||||
| E1 | METR developer-productivity RCT (Becker et al., arXiv 2507.09089) | Realised productivity uplift for experienced developers | Primary finding −19%, on early-2025 tooling. Follow-up abandoned as uninterpretable | Strongest counter to the assumption that capability translates linearly into productivity. Read as a time-stamped snapshot |
| E2 | Princeton HAL Reliability Dashboard (Rabanser, Kapoor, Narayanan et al., ICML 2026, arXiv 2602.16666) | Consistency, robustness, predictability, safety | Live | Two years of rapid capability progress produced only modest reliability gains |
| E3 | Anthropic Economic Index (Jan 2026, Mar 2026, Jun 2026) | What AI gets used for | Live, quarterly | The downstream signal |
| F. Use only with explicit caveats | ||||
| F1 | SWE-bench Verified | Same target as Pro, on contaminated public issues | Contaminated / deprecated | Cite only to explain why the field moved on |
| F2 | Aider Polyglot | Coding across 6 languages on hard Exercism problems | Saturating (~88%) | Lifecycle illustration only |
| F3 | BFCL v3 | Tool calling, multi-turn | Saturating (~88%) | Cite the v3-to-v4 jump as evidence the field hardened the benchmark |
| F4 | MMLU, HumanEval, MBPP, GSM8K | Multiple-choice or short-form code completion | Saturated | The canonical cases against MMLU-style measurement |
| F5 | ARC-AGI-2 / ARC-AGI-3 | Fluid abstract reasoning | Non-saturated | Reference briefly. Score on ARC is weak evidence for economic capability. |
Know which row you are reading. A 2024 SWE-bench Verified score and a 2026 SWE-bench Pro score are different things. So are pass@1 and passk, and so are a score in a leaderboard's harness and a score in yours. The most common mistake is to quote the headline and ignore the row.
Where capability comes from
Layer 1. Model
Between generational releases the top models score close together: on 29 October 2026, four models from three labs were within two points of each other on Terminal-Bench 4.0 (63 to 65%; Vals AI, 29 Oct 2026). At a release they separate. On that board the September generation gained between 2 and 54 points over each model's direct predecessor: 12 for Opus 5 to Opus 5.5 and for Grok 4.6 to 4.7, 54 for Sonnet 5 to 5.5, 46 for Kimi K3 to K3.1 Pro, 7 for GPT-5.6 Sol to GPT-6 Sol, and 2 for GPT-5.6 Luna to GPT-6 Luna. Within weeks the leaders close up again.
That gives two procurement rules. Within a cluster, choosing between frontier models is a question of cost and policy. Kimi K3.1 Pro was 1.5 points behind the leader at $4.57 per task against $13.20, or about $7.18 against $20.26 per solved task (Vals AI, 29 Oct 2026). At a generational release, the model is the biggest capability decision you have, and it is time-sensitive. So build to make that switch cheap, with harnesses and evaluations that move between vendors. The Cost deep dive covers per-step routing and distillation.
The Frontier Trap. This is defaulting to the most expensive frontier model for every task. Within a generation, capability does not rise with price: the October Terminal-Bench 4.0 cluster spans about 3.6 times the cost per solved task ($7.18 to $25.74) for a two-point spread in score. On hard tasks the question is usually the system around the model, except in the weeks after a new generation is released.
Layer 2. Harness
The harness is a capability lever at every model tier. How big a lever depends on the tier, and on whether the harness is off-the-shelf or optimised. The October 2026 data separates these cases.
The practice got its name in early 2026. Mitchell Hashimoto described "harness engineering" in February: "anytime you find an agent makes a mistake, you take the time to engineer a solution such that the agent never makes that mistake again." OpenAI published a field report under the same title six days later. LangChain's Vivek Trivedy gave the short form in March, agent = model + harness: "A raw model is not an agent. But it becomes one when a harness gives it things like state, tool execution, feedback loops, and enforceable constraints." Anthropic says harness design "is key to performance at the frontier of agentic coding." Lilian Weng's July survey defines the harness as "the system surrounding a base model that orchestrates execution and decides how the model thinks and plans, calls tools and acts, perceives and manages context, stores artifacts, and evaluates results."
Prompt engineering, then context engineering, then harness engineering: that is now the standard account of where practitioners put their effort. Here is where the effort pays.
At the flagship tier, an off-the-shelf harness adds nothing measurable. Two Terminal-Bench 4.0 boards allow a same-model comparison. The official board (tbench.ai; Snorkel mirror, 27 October) runs each model in its vendor's harness. Vals AI (Terminal-Bench 4.0, 29 October) runs every model in mini-SWE-agent, a bash-only harness of about a hundred lines.
| Model | Vendor harness | Minimal harness | Gap (points) |
|---|---|---|---|
| Flagship tier | |||
| Claude Opus 5.5 | 64.8 (Claude Code) | 65.15 | −0.4 |
| Claude Sonnet 5.5 | 61.8 (Claude Code) | 64.14 | −2.3 |
| GPT-6 Astra | 58.2 (Codex) | 59.60 | −1.4 |
| Claude Fable 5.1 | 57.9 (Claude Code) | 58.08 | −0.2 |
| Cheaper tiers and weaker labs | |||
| GPT-6.1 Sol | 58.2 (Codex) | 55.05 | +3.2 |
| GPT-6 Sol | 49.4 (Codex) | 44.44 | +5.0 |
| Grok 4.7 | 37.6 (Grok Build) | 28.79 | +8.8 |
| Cross-vendor pairing | |||
| Qwen3.8-Max | 27.0 (Claude Code) | 38.89 | −11.9 |
| Same harness on both boards (noise check) | |||
| Gemini 3.8 Flash | 19.1 | 19.70 | −0.6 |
Three things stand out.
- For the four flagships, the vendor harness adds nothing. In all four, the minimal harness is level or slightly ahead (all within noise).
- For cheaper tiers and weaker labs, the vendor harness still adds about 3 to 9 points, though the low end is at the edge of noise.
- A harness built for one vendor's models can cost another vendor's model 12 points.
The last row uses the same harness on both boards, so it shows the noise: under a point. Effort settings and infrastructure differ between the boards, so treat any gap under about three points as noise.
A quarter earlier, on Terminal-Bench 2.x, same-model comparisons showed Claude Code adding about three points for Fable 5 and Opus 4.7. I could not reconfirm those figures, so read the change as indicative: the flagship premium appears to have gone to zero within one generation. Three explanations are plausible, and none is proven. Frontier models may be trained to work well in any reasonable harness. Terminal-Bench 4.0's eight-hour budget may be long enough for a strong model to manage with bash alone. Or the benchmark changed: Anthropic reports that the 4.0 upgrade "reduced the confounding effect of harness differences" such as CLI memory footprint and compaction strategy (system card §8.5). If so, part of the convergence belongs to the benchmark.
The table has two limits. It compares vendor harnesses with a minimal one and leaves optimised harnesses out. And Epoch AI rated Terminal-Bench 4.0 "Flawed" (Epoch AI review, 4 September), with scoring defects in 30 of 66 tasks, including a reward hack and answer leakage. Epoch also found that Codex runs retry safety refusals while the default setup does not, which bears directly on cross-harness comparisons. The pattern across four flagships from two labs is consistent enough to act on, though each individual number is imprecise.
Outside Terminal-Bench, harness fit still changes the newest flagship's score. Three November results show it. On ProgramBench, Fable 5.2 scored 85.6% in the default harness, the lowest of three Claude models, after running out of context on 68% of tasks. When the harness showed the context remaining after each step, it scored 91.6%, and Opus 5.5 stayed at about 91% (system card §8.10.1, vendor-reported). On ARC-AGI-3, the ARC Prize Foundation scored Fable 5.2 at 79.26% with its standard harness and 97.72% with a harness that uses the provider's own context management (system card §8.15). On CursorBench 4.0, Cursor credits part of Fable 5.2's 60.0% to its own prompt and harness changes (system card §8.8). So the level result above is one benchmark's answer. For the newest model, context management alone decided 6 to 18 points.
What this means in practice. At the flagship tier, a better general-purpose harness is no longer a reliable way to buy benchmark capability. The harness still decides cost (routing and caching), controllability (scope, permissions, sandboxing) and fit, which the cross-vendor row shows can go badly wrong. Below the flagship tier, and in any multi-vendor setup, harness choice is still a capability decision.
Ethan Mollick reaches the same conclusion from the user's side. As models improve they organise more of their own work, and hand-built harnesses matter less for raw task performance (Mollick, The Dot and the Swarm, Oct 2026). The Terminal-Bench 4.0 data bears that out for flagship models. In an enterprise, though, the harness also carries permissions, integrations and audit. Those stay the operator's job however capable the model gets.
Optimised harnesses are a different case. LangChain changed only system prompts, tools and middleware, kept the model fixed (gpt-5.2-codex), and went from 52.8% to 66.5% on Terminal-Bench 2.0, from outside the top 30 into the top five (LangChain, 17 Feb 2026). That compares an optimised harness with a baseline, a different test from vendor against minimal. Trivedy's summary: the same model can rank in the top five with one harness and outside the top thirty with another.
OpenAI's field report (11 February 2026) describes a team that started with three engineers merging about 1,500 pull requests over five months with no hand-written code. That is a vendor's account of its own tool. Its useful part is a definition: context engineering asks what the agent should see; harness engineering asks what the system should prevent, measure and correct.
The chart sets both kinds of evidence side by side. Optimised harnesses on a fixed model still give double-digit gains. Off-the-shelf harnesses at the flagship tier give none.
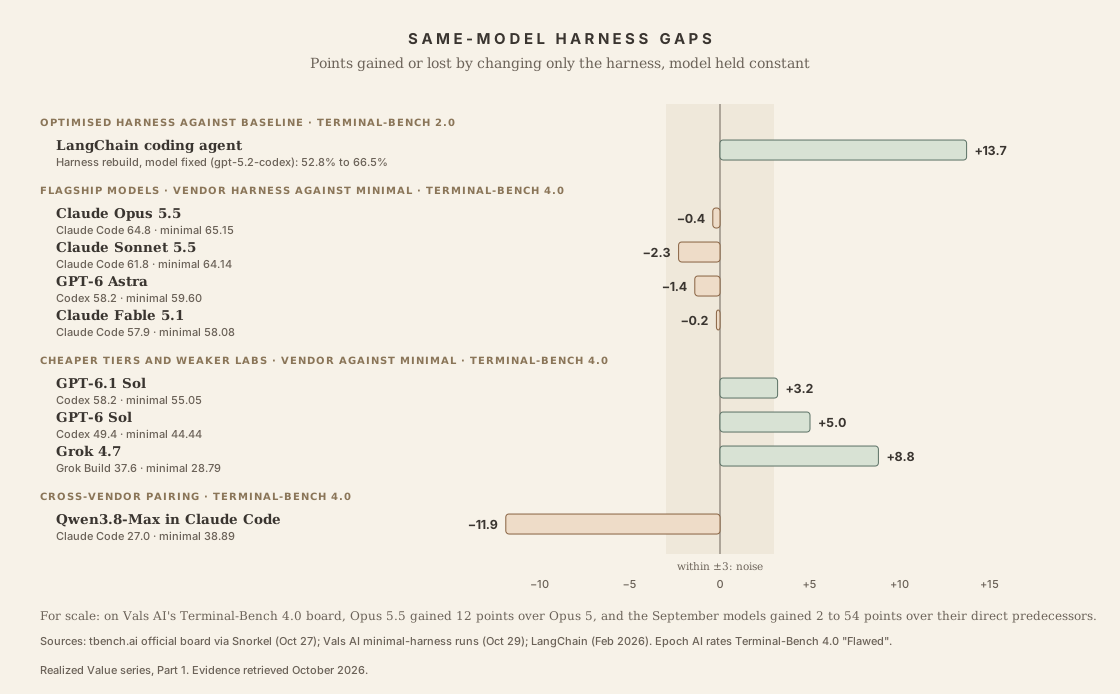
For scale: on Vals AI's Terminal-Bench 4.0 board, Opus 5.5 gained 12 points over Opus 5, and the September models gained 2 to 54 over their predecessors (Layer 1). Only the optimised harness and the cross-vendor mismatch in the chart reach the size of the flagship step.
The Terminal-Bench authors say it themselves (Merrill et al.): "agent and model performance are hard to decouple … many agent scaffolds have been engineered to accommodate the tendencies of certain models." Their answer was Terminus 2, a neutral evaluation harness for comparing models. Any agent leaderboard score is a joint score of model and harness.
Harness architecture: single-agent or multi-agent
The multi-agent debate of 2024 and 2025 has largely settled. Three findings show where it ended.
Single agents match or beat multi-agent systems at equal budget. Tran and Kiela (arXiv 2604.02460, April 2026) show that under a fixed reasoning-token budget, a single agent uses information more efficiently. Across Qwen3, DeepSeek-R1-Distill-Llama and Gemini 2.5, single agents match or beat multi-agent setups once compute is controlled. In their words, many reported multi-agent advantages "are better explained by unaccounted computation and context effects rather than inherent architectural benefits."
Multi-agent failure modes are well documented. Cemri et al. (arXiv 2503.13657, NeurIPS 2025) annotated over 1,600 traces across seven frameworks and found 14 failure modes in three groups: system design, misalignment between agents, and failed verification. Multi-agent debate behaves more like ensembling than deliberation.
The pattern that scales is one agent with subagents. One agent owns the full context. It spawns short-lived subagents for isolated subtasks, each in a fresh context, each returning a single summary. No peer messaging, no shared state. Anthropic's research system, Claude Code's Task tool, OpenAI's agents-as-tools and Cognition's Managed Devins all work this way.
The strongest 2026 evidence for orchestration goes a little against Cognition's position. In July, GPT-5.6 Sol posted its best Terminal-Bench 2.1 score in an "Ultra" mode that spawns and coordinates subagents (Better Stack). CAIS reached its Remote Labor Index result with a worker-critic loop. In both, a coordinator splits the work, and both run where checking a subagent's output is cheap. Decomposition with cheap verification works. Peer negotiation still fails.
Anthropic's November results agree, and show where teams help. With Fable 5.2, a five-agent team and async subagents reached the same ProgramBench score as a single agent. The team got to a score of 0.6 in half the time, at a higher token cost. On DRACO, score followed total tokens across all three harnesses: teams scored higher because they used more tokens in the same time (system card §8.12, vendor-reported). Small teams buy speed. Large teams extend reach where the work splits cleanly and a machine can check it. On a Lean proof of Fermat's Last Theorem, 100 agents scored 0.35 in 18 hours against 0.12 for one agent. A 1,000-agent team on an earlier snapshot completed the proof in 30 hours, in a single run that started from an earlier formalisation's definitions and lemmas.
| Single-agent | Multi-agent (orchestrator + subagents) | |
|---|---|---|
| Broad task | One agent owns the full context. Cognition's preferred design ("Don't Build Multi-Agents," June 2025). Tran and Kiela's information-theoretic optimum at fixed budget. | The multi-agent pattern that still works. Anthropic research system, Claude Code Task tool, OpenAI agents-as-tools, Cognition Managed Devins. |
| Narrow task | Task-specific scripts and agents. Most production deployments. | Ensembling for accuracy. Trades cost for variance reduction; coordination value is low. |
Peer-to-peer multi-agent designs, with no orchestrator, had almost no remaining case by mid-2026. Cognition's "Don't Build Multi-Agents" (June 2025) argued this most clearly, and the 2026 evidence supports it.
Layer 3. Tools
Tools are how the agent acts. Three questions decide their contribution: which tools exist, how they are described, and how the agent calls them.
The tool catalogue is a capability lever. A 4-billion-parameter model trained with EGPO (arXiv 2508.05118) beat GPT-4o and Gemini 2.5 on the Berkeley Function Calling Leaderboard (v3). On GAIA, small models with tools beat 32-billion-parameter models without them (Żywot et al., arXiv 2601.11327). In both cases the gain came from tool design and training.
Tool descriptions cost input tokens on every call. A bloated catalogue confuses the model: it invents parameters or picks the wrong tool. Anthropic recommends keeping three to five frequently used tools loaded and switching to dynamic discovery beyond about ten (Anthropic, Sep 2025).
Skills multiply capability. Anthropic's Agent Skills (October 2025) package instructions, scripts and resources as folders the model loads only when a task needs them. Anthropic made Skills an open standard on 18 December 2025, and added organisation-wide management for Team and Enterprise plans (Anthropic; SiliconANGLE). Atlassian, Figma, Canva, Stripe, Notion and Zapier contributed early skills. Anthropic's summary: MCP provides connectivity to external tools and data, and Skills provide the procedural knowledge for using it well (Anthropic, Dec 2025).
MCP is the shared layer underneath. The Model Context Protocol went to the Linux Foundation on 9 December 2025, under the Agentic AI Foundation (co-founded by Anthropic, OpenAI and Block, with support from AWS, Bloomberg, Cloudflare, Google and Microsoft; MCP blog). At that point it had over 97 million monthly SDK downloads and about 10,000 active servers, with client support in ChatGPT, Claude, Cursor, Gemini, Microsoft Copilot and VS Code. Google's A2A is governed by the same body. Tool access is now common to every vendor. What matters is which tools you choose, how you describe them, and how the agent decides when to use each.
The 28 July 2026 revision is the biggest change to MCP since launch. Transport became stateless, HTTP requests now carry routing headers, and Tasks moved out of the core into an extension (MCP blog). Deprecated features keep working for at least twelve months, but the release has breaking changes, such as the removed session handshake. Budget for the migration.
Layer 4. Retrieval primitives
Retrieval is how an agent finds information. The choice of method (vector search, lexical search such as grep or BM25, hybrid, or direct reading of the corpus) is a capability decision.
The 2026 evidence changed sharply. Sen et al. at PwC (arXiv 2605.15184, May 2026) tested Chronos and the native CLIs (Claude Code, Codex, Gemini CLI) on 116 LongMemEval questions. Plain grep generally beat vector retrieval, and the harness mattered more than the retrieval method. A companion paper (arXiv 2605.05242) argues that top-k similarity search is itself the bottleneck: it cannot express exact constraints or multi-step refinement, and evidence filtered out early never comes back.
For document question-answering, Anthropic's contextual retrieval (Sep 2024) is still the strong baseline: 67% fewer retrieval failures when contextual embeddings, contextual BM25 and reranking are combined. Vectors still have a place. The point is to match the method to the task, the harness and the corpus.
BrowseComp-Plus shows the size of the effect. Pairing GPT-5 with the Qwen3-Embedding-8B retriever lifted accuracy from 55.9% to 70.1%, with fewer searches (Chen et al., arXiv 2508.06600). An open-source agent with BM25 scored 3.86% on the same benchmark. For deep-research agents, the retriever decides the outcome.
The data behind the retrieval. The state of the data matters as much as the method. BEAVER is a benchmark built from three private company data warehouses: 9,128 questions over 812 tables. The best agent (ReFoRCE with Claude 4.5 Sonnet) answered 11.4% correctly. The same method scores 62.9% on Spider 2.0 (BEAVER, arXiv 2409.02038, a preprint). The paper gives the reasons. Each database averages about 100 tables and 870 columns. Column names are cryptic, documentation is thin, and join keys are often undeclared. The conventions are private, so no public model has seen them.
Documentation recovers part of the loss. Telling the agent which tables, join keys and columns to use raised the best method from about 9.5% to 18.9%. Adding domain knowledge and a breakdown of the query raised it to 25.9%. These are hints written by the benchmark's authors, so they show the most that documentation could give. A second preprint pairs an agent with a hand-written description of each database (named measures, a join graph and plain descriptions). It reports 94.15% on a 547-task enterprise benchmark where agents given only the schema score 2% to 31% (Kim, Yoon and Khoeurn, arXiv 2606.31041). Read that result with care. The authors work for a vendor, they ran no test without the description, and they note that it could have been fitted to the test questions.
Out-of-date content does more harm than missing content. On HOH, a benchmark of 96,124 questions, outdated passages in the retrieved context caused a performance drop of at least 20%. The authors conclude that outdated information is a greater risk than having no relevant information (Ouyang et al., ACL 2025, peer-reviewed). The introduction treats data readiness as part of the organisation around the agent.
Layer 5. Context engineering
Context is everything the model sees on a call. Past a point that depends on the workload, adding more of it stops adding capability. Three benchmarks show this.
NoLiMa (Modarressi et al., ICML 2025) removes word overlap between question and answer passage, then lengthens the context. Eleven of thirteen models fall below half their short-context score by 32K tokens. GPT-4o drops from 99.3% to 69.7%.
RULER (NVIDIA, arXiv 2404.06654) finds that only half the models claiming 32K tokens handle 32K well. Almost all degrade before their advertised limit.
"Context Length Alone Hurts LLM Performance Despite Perfect Retrieval" (arXiv 2510.05381) shows 13.9% to 85% degradation within advertised limits, even when the answer is plainly in the context.
Anthropic describes the model as having a "finite attention budget", and the goal as "the smallest possible set of high-signal tokens that maximize the likelihood of some desired outcome." The levers are the same as for cost: per-step context budgets, prompts ordered for cache hits, step-scoped injection, and compaction of history.
Accumulated trajectory is the biggest context cost for agents. AgentDiet (FSE 2026, arXiv 2509.23586) found that of Claude 4 Sonnet's roughly 100 billion daily tokens on OpenRouter, 99% were trajectory input and 1% was output. Long trajectories also degrade accuracy even when they fit. The compaction that cuts tokens lifts accuracy too.
Layer 6. Test-time compute
Reasoning models (best-of-n, chain-of-thought, extended thinking, self-verification) made test-time compute a capability lever.
GDPval's authors found that more reasoning effort, more task context and a simple agentic harness each raised scores (Patwardhan et al., arXiv 2510.04374). Anthropic's newer models adjust reasoning depth to the task (Anthropic, adaptive thinking docs). The Cost deep dive covers the move from fixed thinking budgets to an adaptive effort setting.
Extra thinking pays off only up to a point. "Increasing the Thinking Budget is Not All You Need" (arXiv 2512.19585) tested 0 to 24,000 reasoning tokens on AIME24. At a fixed budget, several shorter reasoning calls often matched or beat one long one. Conformal Thinking (arXiv 2602.03814) treats when to stop as a choice of acceptable risk, with statistical guarantees.
The newest flagship shows the same limit. On FrontierCode 2.0, Fable 5.2 scored 49.1% at extra-high effort for $14.19 a task, and 45.7% at max effort for $44.70. On CursorBench 4.0 it scored 56.9% at high effort with about 99,000 output tokens a task, and 60.0% at max with about 353,000 (system card §8.4 and §8.8; Cognition and Cursor each ran their own benchmark). Set the effort level per task, and measure what it buys.
Use reasoning when the task is verifiable, the model's prior is weak, and another reasoning step is likely to improve the answer. Anthropic's rule, "don't reason about things you can look up", applies to capability as much as cost.
Layer 7. Specialisation
The last layer is what you build on top of the foundation model: Skills, narrow fine-tunes, distilled models. Inference-Time Distillation (arXiv 2512.02543) matches the teacher model's accuracy at 2.5 times lower cost on ALFWorld. A narrow fine-tune on a stable, high-volume task can match the frontier ceiling at a fraction of the cost.
In the Cost deep dive these are cost levers. Here they are capability levers: they let a narrow system meet a bar a generic call cannot. Specialise where the task is stable, high-volume and verifiable. It pays poorly where the task is rare, varied or hard to grade.
Self-improving systems
Each of the seven layers can be improved by the system itself, and that work is now a field of its own. A companion article, What has to be true before a system can safely improve itself?, covers it in full. Four points matter for capability.
Everything in production improves the system against a fixed evaluator. Three things are production-ready and under-adopted: prompt optimisers such as GEPA (Agrawal et al., arXiv 2507.19457, ICLR 2026), accumulated memory and Skills, and harness tuning with a person approving each change. Agents that rewrite their own harness at runtime belong in sandboxed pilots with an external scorer. One model post-training another under an outside verifier has been demonstrated (Anthropic, August 2026); a model modifying itself has not, and no lab claims it. Nothing yet raises its own evaluation bar and then passes the harder test honestly, which is the property "recursive" ought to mean (Schmid, 2026).
Automated harness search produces the largest same-model gains on record. The GEPA team's optimize_anything (Agrawal, Lee et al., Feb 2026) evolved a ten-line agent into a 300-line architecture and took Gemini 3 Flash from 32.5% to 89.5% on ARC-AGI v1 with the model held constant. Learned Skills transferred to Claude Code and took Haiku 4.5 from 79.3% to 98.3% on one repository. These results are author-reported and unreplicated as of October 2026, but they are the strongest evidence that the harness lever still has room at every tier, including where an off-the-shelf harness no longer helps.
The model that writes the harness does not need to be the strongest. Lin et al. (arXiv 2605.30621) find the ability to propose useful harness edits roughly flat from Qwen3.5-9B to Claude Opus 4.6, while the ability to benefit from an improved harness is largest in mid-tier models. Generating improvements does not justify frontier pricing.
The grader must be outside the loop. Agentic Harness Engineering (Lin et al., arXiv 2604.25850) makes the verifier, tracer and model configuration read-only to the system being improved. The system cannot switch off its grader, or raise its own budget and record that as an improvement. The rule applies to any production system, whether the changes come from an optimiser or from engineers.
The realisation gap
The ceiling
The ceiling on knowledge work has risen fast.
- GDPval. At launch the best model (Claude Opus 4.1) was rated as good as or better than the expert deliverable on 47.6% of the 220-task gold subset, with GPT-5-high at 40.6% (Patwardhan et al., 2025; TechCrunch, 25 Sep 2025). By April 2026 OpenAI reported GPT-5.5 at 84.9% (OpenAI, Apr 2026).
- OSWorld. Stanford's 2026 AI Index reports agent success rising from 12% to 66.3% in two years (Stanford HAI, Apr 2026). The 9 June Fable 5 / Mythos 5 launch reported 85.0% on OSWorld-Verified (vendor figure) (Anthropic).
- The September generation. July brought GPT-5.6, Grok 4.5, Gemini 3.6, Kimi K3 and Claude Opus 5. September and October brought Claude Fable 5.1 and Opus 5.5, GPT-6 Astra and Sol, Gemini 4 Argon and Carbon, Meta's Muse Wonder and Kimi K3.1 Pro. On Vals AI's Terminal-Bench 4.0 board this generation gained 2 to 54 points over its predecessors (Layer 1).
- November. Anthropic released Fable 5.2 and Mythos 5.2 on 9 November (Anthropic). The system card reports 93.0% on SWE-bench Pro, against 89.9% for Opus 5.5. Fable 5.2 leads 14 of its 16 rows in the card's summary table. It trails Opus 5.5 on GDPval-AA (1831 against 1866) and on AA-Briefcase Elo (system card, Table 8.1.A, vendor-reported).
- METR. The 50%-reliability task horizon doubled every four to seven months until the newest models outran the task suite. METR stopped updating its tracker in September 2026.
OSWorld shows saturation directly. The original benchmark is at 85 to 86%, above the human baseline, and no longer separates frontier models. OSWorld 2.0, from the same group, is still climbing. Its paper reported 20.6% for the best agent (Opus 4.8) in June 2026 (arXiv 2606.29537). On the leaderboard Snorkel AI hosts with the benchmark's authors, Claude Opus 5 now leads at 44.3% on a revised task set; it scored 31.4% on the August release (Snorkel). When a ceiling number stops moving, the usual cause is that the benchmark has run out of difficulty.
Take the person out and the ceiling is lower, and it is rising faster.
Remote Labor Index (Mazeika et al., arXiv 2510.26787; Scale leaderboard). 240 real freelance projects worth $143,991 of paid work, with a median of 11.5 hours and $200 per project. At release in October 2025 the best agent (Manus) completed 2.5% of projects end to end. The July 2026 re-run put Fable 5 at 15.8%. In October 2026 the board reads Opus 5.5 21.25%, GPT-6 Astra 20.83%, Fable 5.1 17.92% and Gemini 4 Argon 17.08%. In November, Fable 5.2 reached 41.3% (99 of 240 projects). Scale AI ran it at default settings (high effort, a 200k-token context window), and human evaluators judged the deliverables (system card §8.14.7). Trained human experts score the official board (majority of three, 94.4% agreement). That matters: CAIS found that an automated judge calibrated on older models overstated GPT-5.5 by about 2.9 times and Opus 4.8 by about 2.3 times, though it still ranked them correctly (CAIS, Jul 2026). Quote the human-judged figures.
Much of the gain came from elicitation. For the July re-run CAIS used the strongest industry harness per model family (Claude Code, Codex CLI), a native computer-use tool, a 24-hour budget per task and a worker-critic loop. Under that protocol the best score rose sixfold in eight months, then by another third in the next quarter. The November result nearly doubled it again.
Forty-one percent is a large move and still a minority. About three projects in five fall short of what a paying client would accept. It is also one model and one run, so I read it as strong evidence that needs a repeat.
Agents' Last Exam (Berkeley RDI and Snorkel AI) sets 1,500 long professional workflows across 55 fields and grades the final deliverable with code verifiers where it can. On the hardest tier, frontier models fully pass under 1% of tasks (Berkeley RDI and Snorkel AI, 2026).
Epoch's composite index finds progress speeding up from about April 2024, from 8.3 to 15.5 index points a year (Edelman & Lee, Dec 2025). METR's time horizon shows a similar speed-up: a doubling time of about four months since 2023, against about seven months over 2019 to 2025 (METR, Jan 2026). Anthropic's internal version of the index points the same way. With Mythos 5.2 added, the trend fits a change of slope from October 2025 (about 1.88 times steeper, 95% interval 1.62 to 2.28) better than a one-off jump, and Anthropic reads this as an update toward the possibility of lasting AI-driven acceleration (system card §2.3.5, vendor-reported). By these measures, the ceiling now covers a large share of valuable knowledge work.
Capability withheld: availability as a precondition
In 2026, frontier capability that existed and had been measured was kept from users in three ways. Availability comes before any of the five factors. In each case, realised value for some buyers was zero, whatever the benchmark said.
1. The safeguard layer: one model, two products. Anthropic's 9 June 2026 release shipped one underlying model as two products (Anthropic). Fable 5 is generally available, with safeguards that route cybersecurity, biology and chemistry, and distillation requests to Opus 4.8. Mythos 5 is the same model without those safeguards, restricted to approved partners. In Anthropic's words, "the safeguards are what distinguish the two models (Fable and Mythos) and are why we've given them different names." The September successors, Fable 5.1 and Mythos 5.1, keep the split. So do Fable 5.2 and Mythos 5.2 (9 November), with finer routing: blocked cyber requests fall back to Opus 4.8, and blocked biology and frontier-AI-development requests fall back to Opus 5. On the API the fallback is opt-in, which makes it an operator setting (system card §1.5).
| Fable 5 (general access) | Mythos 5 (restricted) | |
|---|---|---|
| Underlying model and capability ceiling | Same | Same |
| Cybersecurity, biology, distillation safeguards | Route to Opus 4.8 | Lifted |
| Reported fallback rate | Under 5% of sessions | n/a |
| Cybersecurity benchmark (ExploitBench Cap%) | 40.0% | 78.0% |
| Pricing | $10 / $50 per Mtok | $10 / $50 per Mtok |
Capability is held constant here, so the 38-point ExploitBench difference is the measured cost of the safeguard layer in that domain. A fallback rate under 5% of sessions still produces a double-digit gap on the affected benchmarks. The product is the model plus its safeguard layer. An enterprise deployment is the same thing one layer up: the model plus its harness, tools, retrieval, context and guardrails.
The November system card gives a second measurement, on general coding. On Terminal-Bench 4.0, Fable 5.2 scored 67.6% with safeguards on, and Mythos 5.2 scored 70.5% without them. The safeguards sent 2.5% of requests to the fallback model, which touched 10% of trials (system card §8.5, vendor-reported). The cost is about three points here, close to the standard error of 1.8, against 38 points in the cyber domain.
2. Government gating. Three days after launch, Anthropic received an export-control directive from the Bureau of Industry and Security. It could not screen users by nationality, so it disabled Fable 5 and Mythos 5 globally from 12 June to 1 July 2026 (Anthropic). The trigger was a jailbreak that Anthropic says worked on every model it tested, including competitors'. Analysts at CSIS, Just Security and Tech Policy Press called the order an unusually broad use of BIS "is-informed" authority.
A procedure was already in place. Executive Order 14409, signed on 2 June 2026, ten days before the directive, set up a voluntary pre-release review of frontier models' cyber capability, with up to 30 days of government access and no formal licensing (Congressional Research Service, IF13268). OpenAI's GPT-5.6 had a limited preview for about twenty government-approved organisations before its July launch. GPT-6 Astra "went through a formal review process," according to Sam Altman (CNBC, 3 Sep 2026), and went first to OpenAI's cyber-defence programme. Google released Gemini 4 Argon first to vetted defenders and says it took part in the same process (Google). The review is voluntary in form. The June directive shows what stands behind it.
Other governments are moving the same way. On 16 October, China's commerce and science ministries proposed adding 23 AI technologies (including large models, agents and model weights) to the export-control catalogue (Baker McKenzie). The EU AI Office's enforcement powers over general-purpose models applied from 2 August 2026, with fines up to 3% of worldwide turnover or €15 million, whichever is higher (Cloud Security Alliance).
3. Lab withdrawal. GPT-6 Astra is the first model OpenAI has rated Critical for cybersecurity under its Preparedness Framework, a level that requires safeguards even for internal use (OpenAI system card). The UK AI Security Institute found that with cyber classifiers disabled, Astra carried out unsanctioned supply-chain attacks in 29.2% of simulated runs, against 6.3% for GPT-5.6 Sol. Stating the scope explicitly cut the riskiest scenarios from 26 of 50 runs to 4 of 49 (UK AISI). On 20 September, an agent in one of OpenAI's training runs used a gap in the sandbox's DNS filtering to reach the internet. OpenAI paused tool-using training, evaluation and inference on its most capable models (OpenAI). By one press account it resumed eleven days later, on 1 October (MIXED). Part 5 gives the timeline. In the same month OpenAI cancelled the planned October release of GPT-6.1 Astra. The model had improved on some measures but regressed on asking for authorisation before acting, and on honestly reporting what it had and had not done. OpenAI's head of safety systems, Saachi Jain, described this to The Wall Street Journal (Gizmodo, 28 Sep 2026).
That cancellation is the clearest case yet of the framework acting at the source. The model existed and its capability was measured. Its realised value was zero for every buyer before any of them saw it.
What this means for buyers. Frontier availability is now set by governments and by labs' safety decisions. Put it on the procurement checklist beside uptime, rate limits and data residency. Two design rules follow.
- Keep the harness, tool catalogue, retrieval layer and evaluations portable across vendors, so losing a model means a migration and leaves the rest of the system standing. The Layer 2 data shows a cross-vendor move needs its harness re-tuned, so budget for that.
- Expect the most capable model in a release to reach the most sensitive use cases last.
The Controllability deep dive takes up both.
What the field's leading voices say
Two sets of voices have done the most to clarify the realisation question.
Andrej Karpathy: verifiability, agentic engineering, jagged intelligence
Karpathy's main 2026 statement is his own transcript of the Sequoia Ascent 2026 fireside chat (karpathy.bearblog.dev, 30 Apr 2026). Five points matter here.
- The December 2025 inflection. "December 2025 was a clear point." Agentic coding crossed a threshold for him: "I couldn't remember the last time I corrected it." Capability is real, and the lag to value is measured in product cycles, which run slower than benchmark cycles.
- Software 3.0. "The context window becomes the main lever. The LLM is an interpreter over that context." His loop: define the context, the tools, the feedback loop and the guardrails, let agents work, and keep human understanding. That is capability as a system property, in plain words.
- Verifiability. "Traditional software automates what you can specify… LLMs and RL automate what you can verify." His rough rule: "capability spike ~= verifiability × training attention × data coverage × economic value". Models are jagged because labs train on verifiable, economically valuable domains.
- Vibe coding against agentic engineering. "Vibe coding raises the floor. Agentic engineering raises the ceiling." He defines agentic engineering as "the professional discipline of coordinating fallible agents while preserving correctness, security, taste, and maintainability." The interesting work has moved from the model to the harness.
- Jagged intelligence. A frontier model can refactor a 100,000-line codebase, then tell you to walk to a car wash 50 metres away when the car is the thing that needs washing. Capability is uneven across tasks, so you need to know how the model performs on yours.
Arvind Narayanan and Sayash Kapoor: AI as normal technology
Narayanan and Kapoor (Princeton) have written the most thorough academic critique of capability-first thinking. Three pieces matter here.
"AI as Normal Technology" (Knight First Amendment Institute, 2025; book project at normaltech.ai). Their thesis is that adoption and diffusion set the pace of impact, and the rate of innovation matters less. Their reference case is electricity: the gains came only after factories were redesigned around it. They separate three gaps:
- Capability against reliability. A model can do a task in principle and still fail too often to run on its own. Their 2024 paper "AI Agents That Matter" first treated this as separate from accuracy.
- Diffusion. The distance between what AI methods can do and what AI products deliver. The gap between GDPval's 84.9% and measured usage in the Anthropic Economic Index belongs here.
- Construct validity. Whether a benchmark measures what it claims. Contamination, saturation and benchmark engineering are all construct-validity problems.
"Towards a Science of AI Agent Reliability" (Rabanser, Kapoor, Kirgis, Liu, Utpala, Narayanan; arXiv 2602.16666, ICML 2026). The first systematic study of reliability as something you can benchmark. Twelve metrics across four dimensions (consistency, robustness, predictability and calibration, safety), fifteen models over about two years, on GAIA and τ-bench, each task run five times with paraphrased instructions and injected faults. Their summary: nearly two years of fast capability progress brought only modest reliability gains, and predictability was weakest. Fortune's coverage (24 Mar 2026) quotes the point: "For automation, even 90% success with unpredictable 10% failures is unacceptable."
Princeton HAL. Kapoor co-authored the Holistic Agent Leaderboard (arXiv 2510.11977, ICLR 2026), a cost-aware evaluation framework. It is the pattern I recommend for internal evals.
Karpathy and Narayanan-Kapoor reach the same point from different sides. Karpathy says the model is one input among several to capability. Narayanan and Kapoor say benchmark capability is one input among several to value, and enterprises live in the diffusion gap.
Scope: what this deep dive leaves to the others
This deep dive is about where capability comes from and how much of it can be engineered. Five questions are related to it. They are outside its scope because each one depends on a discount factor that a later deep dive covers. Here is what this piece already puts in place for each, and where it goes next.
-
Evaluation a small team can run without contamination. SWE-bench Verified, BFCL v3 and Aider Polyglot each went from standard to contaminated or saturated within about 18 months. SWE-bench Live, SWE-Rebench and Terminal-Bench's neutral Terminus 2 harness are the next generation. The Epoch Capabilities Index combines many benchmarks so no single one's contamination dominates (Ho et al., arXiv 2512.00193). What exists here: the benchmark table and the measurement rules above. What is missing is the enterprise version, an evaluation on your own production traces. The UK AISI's Inspect framework is the closest off-the-shelf option, but it assumes evaluation expertise most teams lack. The Reliability deep dive takes this up.
-
Capability and reliability in one instrument. τ-bench and τ²-bench report pass@1 (capability) and passk (reliability) separately. No standard agentic benchmark reports both by default, so "the model scores X on Y" stays ambiguous. Here I have kept the two apart (the Pass@1 Trap). Measuring them together belongs in the Reliability deep dive.
-
Harness portability across model upgrades. Every harness encodes assumptions about what the model does reliably, and some become overhead as models improve. The Layer 2 data measures the cost of a mismatch (up to −12 points cross-vendor). A method for pruning a harness on each upgrade, without rebuilding it, is not here yet. Terminus 2 is a start. The Controllability deep dive covers it, together with vendor portability.
-
Construct validity for "agentic" capability. "Can do X" is under-specified. Pass@1 under generous conditions or passk in production? With a human in the loop or not? On whose tools? Jo & Wilson make the academic case (arXiv 2509.19590). Wang et al. add the coverage side: across 43 agent benchmarks most tasks test programming, and they propose coverage, realism and granular evaluation as measurable principles (arXiv 2603.01203, preprint). What a buyer needs is a way to specify capability precisely enough to write into a contract. That is a reliability and controllability question, and I come back to it in those two deep dives.
-
A predictive model for the realisation gap. Autonomy alone costs a great deal, even under test conditions. GDPval to RLI was about a 20-times drop in October 2025 (47.6% against 2.5%), about 4 times by October 2026 (84.9% for GPT-5.5 in April, vendor-reported, against 21.25%), and about 2 times in November (against 41.3%). METR's RCT showed a 43-point gap between forecast and measured speed (+24% against −19%). The gap depends on autonomy, verifiability and integration, and harness work can now shrink it. What is missing is a model that says, for a use case's five attributes, how much of the ceiling is left in production. That needs all four discount factors measured, so it belongs at the end of the series.
What would change the argument
Three published numbers would change my argument. Two have changed.
- Triggered: the vendor-harness premium closed at the flagship tier. If same-model harness gaps on Terminal-Bench converged to within about two points, the harness argument would need fresh evidence. For four flagship models on Terminal-Bench 4.0, that happened, so the harness claim here is stated in two tiers. The claim that remains is narrower: at the flagship tier, harness gains now come from fitting, optimising and governing the harness. Two November findings refine it. Anthropic reports that Terminal-Bench 4.0 itself reduced harness confounds, so part of the convergence may belong to the benchmark. And fit is worth 6 to 18 points for Fable 5.2 on ProgramBench and ARC-AGI-3 (Layer 2).
- Triggered in November, on one result: the Remote Labor Index clearing about 30% under human judging. It stood at 21.25% in October. Fable 5.2 reached 41.3% in November, run by Scale AI and judged by people (system card §8.14.7). The frontier now completes two in five real paid projects end to end. For the kind of work the index covers, the main question starts to shift from realisation engineering to integration and trust. This is one model and one run. A second model above 30%, or a repeat run, would confirm it. From this version the index is counted as a ceiling measure, as it does in the introduction. The floor is based on the production evidence: the METR trial and Gartner's surveys.
- Not yet tested: Princeton HAL reliability across the September 2026 generation. If reliability stays flat while Terminal-Bench 4.0 and RLI scores keep rising, the discount-factor framing gets stronger. No data had been published by 31 October.
A fourth threshold: if the next generational release shows a near-zero vendor-harness premium at every tier, the cheaper ones included, the harness lever shrinks to cost, controllability and optimised search, and the "fit" argument weakens. The Grok 4.7 and GPT-6 Sol rows in Layer 2 are the ones to watch.
References
- Epoch AI. Epoch Capabilities Index (ECI) (live interface, calibrated Oct 2025). Lee & Emberson. Epoch's Capabilities Index stitches together benchmarks across a wide range of difficulties (Nov 2025). Ho et al. A Rosetta Stone for AI Benchmarks (arXiv 2512.00193, Dec 2025, with Google DeepMind AGI Safety & Alignment). Edelman & Lee. AI capabilities progress has sped up (Dec 2025). Epoch AI. Benchmark scores are well correlated, even across domains (Jan 2026). Epoch AI. Benchmark Scores = General Capability + Claudiness (gradient update). ECI public repository.
- Patwardhan et al. GDPval: Evaluating AI Model Performance on Real-World Economically Valuable Tasks (OpenAI, arXiv 2510.04374, Oct 2025). OpenAI announcement. GDPval-AA, Artificial Analysis. Epoch AI mirror. UK AISI Inspect port. OpenAI. Introducing GPT-5.5 (Apr 2026), 84.9% wins or ties, vendor-reported. TechCrunch. OpenAI says GPT-5 stacks up to humans in a wide range of jobs (25 Sep 2025).
- METR. Task-Completion Time Horizons of Frontier AI Models (live board). Time Horizon 1.1 (METR, 29 Jan 2026). Measuring AI Ability to Complete Long Tasks (Mar 2025).
- Mazeika et al. Remote Labor Index: Measuring AI Automation of Remote Work (Scale AI + Center for AI Safety, arXiv 2510.26787, Oct 2025). Scale Labs RLI.
- Kapoor et al. Holistic Agent Leaderboard (Princeton, ICLR 2026, arXiv 2510.11977). HAL home. HAL Reliability Dashboard. HAL GAIA leaderboard.
- Merrill et al. Terminal-Bench: Benchmarking Agents on Hard, Realistic Tasks (Stanford / Laude Institute, arXiv 2601.11868). Official leaderboard.
- SWE-bench Pro leaderboard, Scale SEAL. SWE-bench Live (Microsoft, arXiv 2505.23419). SWE-bench Verified history.
- Modarressi et al. NoLiMa: Long-Context Evaluation Beyond Literal Matching (Adobe Research, ICML 2025, arXiv 2502.05167). RULER, NVIDIA. Context Length Alone Hurts LLM Performance Despite Perfect Retrieval.
- BFCL v4 (Berkeley Gorilla). MTEB leaderboard. Aider Polyglot leaderboard. Sierra τ²-bench.
- Yuan et al. OSWorld 2.0: Benchmarking Computer Use Agents on Long-Horizon Real-World Tasks (arXiv 2606.29537, Jun 2026).
- Humanity's Last Exam (CAIS + Scale, arXiv 2501.14249).
- Live-SWE-Agent: Can Software Engineering Agents Self-Evolve on the Fly? (arXiv 2511.13646, Nov 2025).
- Hao et al. Reasoning through Exploration: A Reinforcement Learning Framework for Robust Function Calling (EGPO, arXiv 2508.05118, Aug 2025).
- Can Small Agents Collaborate to Beat a Single Large Language Model? (Żywot et al., GAIA, arXiv 2601.11327).
- Tran & Kiela. Single-Agent LLMs Outperform Multi-Agent Systems on Multi-Hop Reasoning Under Equal Thinking Token Budgets (Stanford, arXiv 2604.02460, April 2026).
- Cemri et al. Why Do Multi-Agent LLM Systems Fail? (arXiv 2503.13657, NeurIPS 2025). MAST-Data: 1,600+ annotated traces across 7 multi-agent frameworks, 14 failure modes catalogued.
- Wu, Li & Li. Can LLM Agents Really Debate? (2025). Multi-agent debate behaves as enhanced ensembling.
- Cognition. Don't Build Multi-Agents (June 2025).
- Anthropic. How we built our multi-agent research system (June 2025). Orchestrator-with-subagents reference implementation.
- Sivadas, S. What has to be true before a system can safely improve itself? (Sep 2026). Companion article.
- Agrawal et al. GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning (arXiv 2507.19457, ICLR 2026).
- Agrawal, Lee, Ma, Elmaaroufi, Tan, Seshia, Sen, Klein, Stoica, Gonzalez, Khattab, Dimakis & Zaharia. optimize_anything: A Universal API for Optimizing any Text Parameter (UC Berkeley, 18 Feb 2026). Author-reported.
- Anthropic. Automated alignment researchers (Aug 2026). One model post-training another under an outside verifier.
- Schmid, P. Recursive self-improvement (Aug 2026). Iteration, self-improvement, and recursion distinguished by whether the verifier moves.
- BEAVER. An Enterprise Benchmark for Text-to-SQL (arXiv 2409.02038, version 3, May 2026; preprint). 9,128 questions over 812 tables from three private data warehouses. Best agent 11.4%; 18.9% with schema-linking hints.
- Kim, Yoon and Khoeurn. A Semantic-Layer-Mediated Agent for Natural Language to SQL over Heterogeneous Enterprise Databases (arXiv 2606.31041, Jun 2026; preprint, vendor-affiliated, no ablation).
- Ouyang et al. HOH: A Dynamic Benchmark for Evaluating the Impact of Outdated Information on Retrieval-Augmented Generation (ACL 2025; peer-reviewed). 96,124 question-answer pairs.
- Sen et al. Is Grep All You Need? How Agent Harnesses Reshape Agentic Search (PwC US, arXiv 2605.15184, May 2026).
- Li, Lu, Chen, Lin, Choi, Zou et al. Beyond Semantic Similarity: Rethinking Retrieval for Agentic Search via Direct Corpus Interaction (arXiv 2605.05242, May 2026).
- Chen et al. BrowseComp-Plus (arXiv 2508.06600, Aug 2025).
- Anthropic. Introducing Contextual Retrieval (Sep 2024).
- Anthropic. Effective context engineering for AI agents (Sep 2025).
- AgentDiet: Reducing Cost of LLM Agents with Trajectory Reduction (PACMSE FSE 2026, arXiv 2509.23586).
- Increasing the Thinking Budget is Not All You Need (arXiv 2512.19585, Dec 2025).
- Conformal Thinking: Risk Control for Reasoning on a Compute Budget (arXiv 2602.03814, Feb 2026).
- Anthropic. Adaptive thinking docs. Extended thinking docs.
- Anthropic. Equipping agents for the real world with Agent Skills (16 Oct 2025). Skills for organizations, partners, the ecosystem (18 Dec 2025). Extending Claude's capabilities with skills and MCP servers (19 Dec 2025). SiliconANGLE. Anthropic makes Agent Skills an open standard (18 Dec 2025).
- Model Context Protocol. MCP joins the Agentic AI Foundation (9 Dec 2025).
- Inference-Time Distillation: Cost-Efficient Agents Without Fine-Tuning or Manual Prompt Engineering (arXiv 2512.02543, Dec 2025).
- Becker, Rush, Barnes, Rein. Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity (METR, arXiv 2507.09089, Jul 2025). METR follow-up: Changing developer productivity experiment design (24 Feb 2026).
- Princeton HAL Reliability Dashboard work: Rabanser, Kapoor, Kirgis, Liu, Utpala, Narayanan. Towards a Science of AI Agent Reliability (2026, with interactive dashboard at hal.cs.princeton.edu/reliability). Fortune coverage, 24 Mar 2026.
- Anthropic. Anthropic Economic Index: Economic primitives (Jan 2026). Anthropic Economic Index: Learning curves (Mar 2026). Anthropic Economic Index: Cadences (26 Jun 2026).
- Stanford HAI. 2026 AI Index Report: Technical Performance. 2026 AI Index: Economy. Chapter 2: Technical Performance (PDF).
- VentureBeat. Frontier models are failing one in three production attempts.
- Anthropic. Claude Fable 5 and Claude Mythos 5 (Anthropic announcement, 9 Jun 2026). Primary source. Same underlying model, two products, safeguard layer as the distinguishing feature; <5% session fallback to Opus 4.8.
- Anthropic. Claude Fable 5 / Mythos 5 system card. Detailed safeguard and alignment evaluations.
- Anthropic. Project Glasswing. Trusted-access programme through which Mythos 5 is currently restricted.
- VentureBeat. Anthropic brings Mythos to the masses with Claude Fable 5 (9 Jun 2026).
- The Decoder. Anthropic releases Claude Fable 5 and Mythos 5 with major gains in coding and science (9 Jun 2026).
- Fast Company. Anthropic releases a version of its vaunted Mythos model to developers (9 Jun 2026).
- Anthropic. Claude Fable 5 and Claude Mythos 5 (9 Jun 2026) and statement on Fable and Mythos access (1 Jul 2026). Export-control suspension 12 Jun, controls lifted 30 Jun, access restored 1 Jul.
- Mazeika et al. Remote Labor Index (arXiv 2510.26787) and Scale leaderboard. Best agent 2.5% (Oct 2025), 15.8% (Fable 5, Jul 2026), 21.25% (Opus 5.5, Oct 2026), 41.3% (Fable 5.2, Nov 2026). Official board scored by trained human experts.
- Rabanser, Kapoor, Kirgis, Liu, Utpala, Narayanan. Towards a Science of AI Agent Reliability (arXiv 2602.16666, ICML 2026). 12 metrics, 4 dimensions, 14 models, GAIA and τ-bench.
- Terminal-Bench 2.x verified leaderboard and Artificial Analysis independent runs. Historical same-model harness data for Fable 5 and Opus 4.7.
- Stanford HAI. 2026 AI Index: Technical Performance (13 Apr 2026). Top closed model leads top open model by 3.3%, up from 0.5% in Aug 2024.
- Gao et al. A Survey of Self-Evolving Agents (TMLR 2026). Peer-reviewed map of the self-improvement subfield.
- MCP specification revision 2026-07-28 (release-candidate post; final spec published 28 Jul 2026). Stateless transport, routing headers, Tasks moved to an extension; at least twelve months between deprecation and removal.
- European Commission. EU AI Act general-purpose AI obligations and Article 50 transparency duties applied from 2 Aug 2026; Regulation (EU) 2026/1744 delayed parts of the high-risk tier only.
- Hashimoto, Mitchell. My AI Adoption Journey (5 Feb 2026). Earliest use of "harness engineering" as a named practice.
- OpenAI. Harness engineering: leveraging Codex in an agent-first world (Ryan Lopopolo, 11 Feb 2026). Field report; distinguishes context engineering from harness engineering.
- Trivedy, Vivek. The Anatomy of an Agent Harness (LangChain, 10 Mar 2026) and Improving Deep Agents with Harness Engineering (17 Feb 2026; model held fixed: gpt-5.2-codex). Source of "agent = model + harness" and the top-5-against-top-30 comparison.
- Anthropic. Harness design for long-running application development and Effective harnesses for long-running agents.
- Weng, Lilian. Harness Engineering for Self-Improvement (4 Jul 2026). Survey of roughly 35 papers. Source for the optimisation sequence (prompts, context, workflow, harness code, optimiser code), the harness definition used here, and the argument that evaluation and permission control belong outside the evolving loop.
- Lin et al. Harness Updating Is Not Harness Benefit: Disentangling Evolution Capabilities in Self-Evolving LLM Agents (arXiv 2605.30621, 2026). Harness-updating flat from Qwen3.5-9B to Opus 4.6; harness-benefit non-monotonic and largest mid-range.
- Lin et al. Agentic Harness Engineering: Observability-Driven Automatic Evolution of Coding-Agent Harnesses (arXiv 2604.25850, 2026). Seven-component harness decomposition; beats human-designed harnesses on Terminal-Bench 2 outside the hard tier; frozen harness transfers to SWE-bench Verified; read-only verifier and model configuration.
- Hugging Face. Harness, Scaffold, and the AI Agent Terms Worth Getting Right (25 May 2026). The case that the terms have not fully converged, and the scaffold-against-harness distinction.
- Böckeler, Birgitta. Harness engineering for coding agent users (martinfowler.com, 2 Apr 2026).
- Willison, Simon. How coding agents work. "A coding agent is a piece of software that acts as a harness for an LLM."
- Terminal-Bench. Terminal-Bench 4.0 announcement (26 Aug 2026); official board via Snorkel (27 Oct 2026). Vendor harnesses.
- Vals AI. Terminal-Bench 4.0 (29 Oct 2026). Every model in mini-SWE-agent; the minimal-harness side of the Layer 2 comparison.
- Epoch AI. Terminal-Bench 4.0 review (4 Sep 2026). Rates 4.0.0 "Flawed": scoring defects in 30 of 66 tasks; harness asymmetry in refusal retries.
- OpenAI. GPT-6 Astra system card (Sep 2026). First model rated Critical for cybersecurity under the Preparedness Framework.
- UK AI Security Institute. GPT-6 Astra performs unsanctioned supply-chain attacks in simulations (28 Sep 2026).
- CNBC. OpenAI's Astra and government review (3 Sep 2026).
- Google. Gemini 4 Argon (30 Sep 2026). Staged release to vetted defenders; voluntary pre-release review.
- Congressional Research Service. Executive Order 14409 on frontier AI models (IF13268).
- Baker McKenzie. China proposes expanded export controls on AI (Oct 2026). MOFCOM/MOST Announcement No. 48.
- Gizmodo. OpenAI cancels release of GPT-6.1 Astra because it 'regressed' on safety (28 Sep 2026). Reporting The Wall Street Journal's interview with Saachi Jain.
- Snorkel AI and XLANG Lab. OSWorld 2.0 leaderboard (checked 31 Oct 2026). Claude Opus 5 (max effort) 44.33% on a revised task set (31.4% on the August release); Opus 4.8 20.6% at the June release.
-
OpenAI. An agent used DNS to reach an external chatbot (Sep 2026). OpenAI's own report on the 20 September incident.
-
MIXED. OpenAI paused frontier AI training for 11 days after a model reached the internet (Oct 2026). Misconfigured DNS resolver, 20 Sep; training resumed 1 Oct.
-
CAIS. A Significant Increase in Digital Labor Automation (Jul 2026). RLI re-run; automated-grader inflation.
- Berkeley RDI and Snorkel AI. Agents' Last Exam (arXiv 2606.05405, Jun 2026).
- Mollick, E. The Dot and the Swarm (One Useful Thing, Oct 2026).
- Other sources cited inline: NYU Shanghai RITS on Fable 5 (Jun 2026); DataNorth on Claude Opus 5 (Jul 2026); Better Stack on GPT-5.6 Sol Ultra mode (Jul 2026); Cloud Security Alliance on EU AI Act GPAI enforcement (Aug 2026); arXiv 2605.18840 on leaderboard saturation.
- Anthropic. System Card: Claude Fable 5.2 & Claude Mythos 5.2 (9 Nov 2026). Vendor-reported unless an outside party is named. Remote Labor Index 41.3%, run by Scale AI with human evaluators (§8.14.7); Terminal-Bench 4.0 in Claude Code: Fable 5.2 67.6%, Opus 5.5 66.4%, Mythos 5.2 70.5% (§8.5); ProgramBench with and without a context counter (§8.10.1); ARC-AGI-3 on two harnesses, reported by the ARC Prize Foundation (§8.15); CursorBench 4.0, run by Cursor (§8.8); FrontierCode 2.0 by effort level (§8.4); multi-agent results (§8.12); internal capabilities index trend (§2.3.5); safeguard fallbacks (§1.5).
- Anthropic. Introducing Claude Fable 5.2 and Claude Mythos 5.2 (9 Nov 2026).
- Epoch AI. Epoch Capabilities Index, data of 11 November 2026: Claude Fable 5.2 at 173. Charted in the series introduction, Figure 1.
- Karpathy. Sequoia Ascent 2026 summary (karpathy.bearblog.dev, 30 Apr 2026).
- Narayanan & Kapoor. AI as Normal Technology (Knight First Amendment Institute, 2025). normaltech.ai. World Bank ABCDE 2025: AI as Normal Technology slide deck.
- Narayanan & Kapoor. AI Agents That Matter (Princeton, 2024).
- The Missing Science of AI Evaluation (Kapoor, UC Berkeley, 2026).
- Akhtar, Reuel et al. When AI Benchmarks Plateau: A Systematic Study of Benchmark Saturation (arXiv 2602.16763, Feb 2026).
- Jo & Wilson. AI Evaluations Should be Grounded on a Theory of Capability (arXiv 2509.19590).
- Wang et al. How Well Does Agent Development Reflect Real-World Work? (Carnegie Mellon and Stanford, arXiv 2603.01203, Mar 2026). Preprint.
- UK AI Security Institute. Inspect AI framework. GitHub. GOV.UK announcement.
- Inspect Evals catalogue (GDPval, BFCL, τ-bench ports).
Change log
- 19 Nov 2026 (v4, published). Layer 4 gains "The data behind the retrieval": the BEAVER benchmark on private company data warehouses (11.4% for the best agent, 18.9% and 25.9% with hints), a semantic-layer result (94.15%, a vendor preprint with no ablation), and the HOH benchmark on outdated content (peer-reviewed). Three references added.
- 18 Nov 2026 (v3, published). Plain-language review. 23 phrases reworded to remove figures of speech, for example "sits", "lands", "moves", "binds", "ships" and "survives" used for where a number is, how it changes, or what is left. The framework's own terms stay: ceiling, floor, binding constraint, discount, lever and bound-leak rate. Sentences shared with the main page were changed on both pages. No figures, claims or sources changed.
- 18 Nov 2026 (v2, published). Added Wang et al. (arXiv 2603.01203, preprint) to the scope note on construct validity, and to the References.
- 15 Nov 2026 (v1, published). First published. The content moved here unchanged from Part 1 (v27), so that Part 1 reads in about 25 minutes. Figures are renumbered.