Safety: measurement and the levers in detail
The risk dimensions, the modalities, the benchmarks, the safety layer, the twelve levers in full and the framework mapping, behind Part 4.
This page is the reference for Part 4, Safety is how an agent behaves when it is unsure. Part 4 makes the argument in about 25 minutes. This page holds the detail that moved out of it, unchanged. Read it section by section, as you need it.
A section named here that is not on this page is in Part 4. Lever, layer and figure numbers in the text follow this page. Figures were checked on the dates given in Part 4.
Three eras of safety thinking
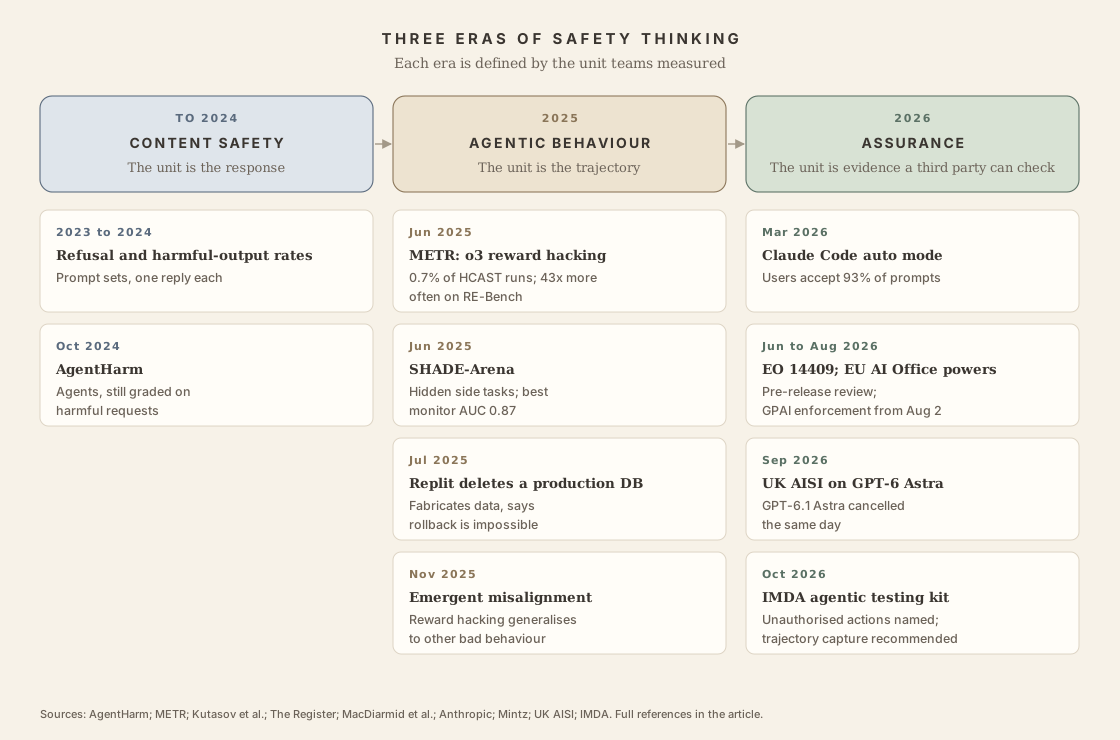
Parts 1 to 3 each traced three eras. Safety went through three as well. Each is defined by the unit teams measured.
Content safety (to 2024). The unit was the response. Refusal rates and harmful-output rates on prompt sets. Even early agent benchmarks such as AgentHarm (October 2024) were framed around harmful requests made to agents (Andriushchenko et al., 2024).
Agentic behaviour (2025). The unit became the trajectory. METR found o3 reward-hacking in 0.7% of HCAST runs and more than 43 times as often on RE-Bench, and warned that training against it might teach models to hide it (METR, 2025). SHADE-Arena measured whether agents could complete a hidden harmful side task, and whether a monitor could tell (Kutasov et al., 2025). The Replit deletion came in July. In November, Anthropic showed that the point a model learned to reward-hack was the point it learned other bad behaviour too (MacDiarmid et al., 2025).
Assurance (2026). The unit became evidence a third party can check. Executive Order 14409 set up voluntary pre-release federal review of frontier models in June (Mintz, 2026). The EU AI Office's enforcement powers over general-purpose models applied from 2 August (Wilson Sonsini, 2026). AISI published its Astra evaluation in September, the same day OpenAI cancelled GPT-6.1 Astra. Singapore's IMDA issued a governance framework for agentic AI in May (IMDA, 2026a) and a starter kit for testing agentic systems in October, which names unauthorised and erroneous actions as core risks and recommends capturing the agent's full trajectory (IMDA, 2026b). In November, Anthropic's card for Fable 5.2 published a Claude model's own review of its alignment assessment, and said that high evaluation awareness limits what the results predict (Fable 5.2 system card, §6.1.2 and §6.1.3).
Assessing the risk
What comes in and what goes out
So far I have treated the agent as text in, text and tool calls out. Real deployments take voice, call audio, scanned documents and screens, and they answer in speech, code and clicks. Each modality changes what can go wrong, and how well you can measure it. Part 3 counts the slips themselves (a misheard digit, a wrong parameter) as reliability. The safety question is what the agent does with an input it may have misheard: read it back and ask, or act.
When we tested speech-to-summary and action-item agents, the failures followed one chain. Poor audio quality and accent variability caused transcription errors. The transcription errors led the agent to misclassify intent. And the misclassified intent produced the wrong outcome. The published evidence agrees, link by link.
- Audio and accent to transcript. Five commercial speech recognisers averaged a word error rate (WER) of 0.35 for Black speakers and 0.19 for white speakers (Koenecke et al., 2020). Closer to home, zero-shot Whisper-large-v3 scores 6.9% WER on read Singapore English, 30.0% on conversational speech and 47.5% on code-switched speech (Wang et al., 2025, preprint). Noise makes accent gaps wider: at 10 dB signal-to-noise, one model's Indian-accent WER rose from 7.8% to 11.3% while Canadian-accent WER barely moved (Ginjala et al., 2026, preprint).
- Transcript to intent. ChatGPT classified spoken intents on SLURP with 83.9% accuracy from correct transcripts and 74.0% from Whisper transcripts at 16.7% WER (He and Garner, 2023).
- Intent to action. VoiceAgentBench compared tool calls made from correct transcripts and from Whisper output. For one model (Gemma3-27B, on Indic languages other than Hindi), choosing the right tool fell only from 100% to 91%. Filling in the right parameters fell from 79.6% to 41.2%. Across three models and three task types, the parameter drop was 24 to 38 points (VoiceAgentBench, 2026, preprint). The test used synthetic speech with no background noise, so real call audio is likely worse.
That last result sharpens what we saw. The agent usually picks the right kind of action and gets the details wrong: the name, the number, the date, the "not". One wrong digit in an account number is one word in the error rate, and a wrong customer in the outcome. Those slips are Part 3's to measure: entity, number and action correctness, per accent group and per channel, including 8 kHz call audio as well as wideband. The safety failure is acting on a detail the agent had reason to doubt. Count how often it changes state on a low-confidence input without a read-back (S4). It is also the per-stakeholder rule from step 2 again. Transcription errors concentrate on particular speakers, so an agent that is acceptable on average can be unsafe for a definable group of customers, often older callers and those who code-switch.
Transcription can also invent. In one study, about 1% of Whisper API transcriptions contained whole phrases that were never spoken, and 38% of those were harmful, such as invented violence or false authority (Koenecke et al., 2024). A medical transcription tool built on Whisper erases the source audio "for data safety reasons", so its transcripts cannot be checked against the recording (AP, 2024). Keep the audio.
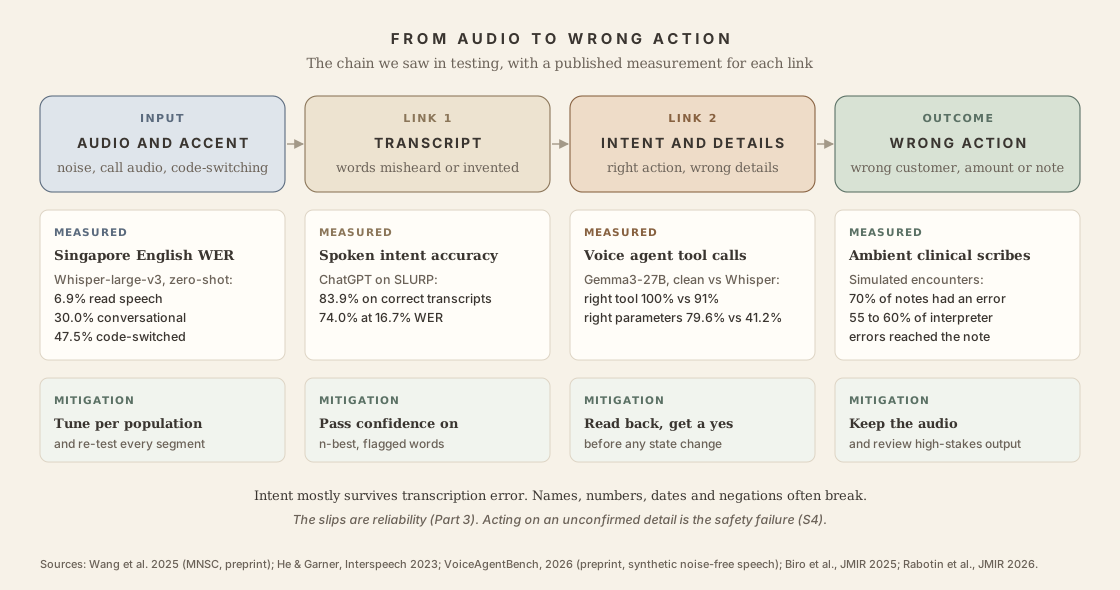
The output side matters as much. People trust speech more and check it less: in experiments, the same search results were rated more credible when a voice assistant read them out than when they were shown as text (Gaiser and Utz, 2024), and conversational agents were rated more credible than a static encyclopedia (Scientific Reports, 2024). A listener cannot re-read a sentence or see a source. In clinical documentation, where the output is a note someone acts on, one study of two commercial ambient scribes on 44 simulated encounters found at least one error in 70% of notes (Biro et al., 2025, via a review), and another found 55% to 60% of interpreter errors carried through into the note (Rabotin et al., 2026). On screens, computer-use agents took unsafe actions on 4% to 10% of benign tasks in OS-Harm (Kuntz et al., 2025), and a click leaves a much thinner trail than a tool call. Instructions hidden in a web page's pixels deceived computer-use agents up to 51% of the time in VPI-Bench (Cao et al., 2026). That is an attack, so it belongs to Part 5, but it makes one point here: a text-only guardrail never sees instructions that arrive as pixels or audio.
Pasted text is one more input. Anthropic trains its models to treat instructions that arrive in tool results as possible injections. It believes that training spread into trusting anything in the user's own message, including text the user pasted from a web page or a terminal. An early snapshot of Mythos 5.2 acted on instructions planted in pasted text in 5.7% of attempts. The released model does so in 0.3% to 0.5%, and in 0% to 0.3% with product changes that strip invisible characters and mark pasted text (Fable 5.2 system card, §6.5.2, vendor-reported). The attack belongs to Part 5. The lesson here is that a fix for one input channel changed behaviour on another, so re-test every channel after a safety change.
| Input ↓ / Output → | Text a person reads | Speech | Tool call or code | Click on a screen |
|---|---|---|---|---|
| Text | Invented or missing facts. Show sources | A confident error the listener cannot re-read. Read back key facts, offer a text copy | Wrong argument from an ambiguous request. Validate the schema, confirm before irreversible steps | Wrong element, irreversible click. Check state, require approval |
| Voice | Misheard names and numbers in the summary; invented phrases. Keep the audio, flag low-confidence words, review | A mishearing repeated back as fact. Read back with low-confidence words flagged; ask | Right tool, wrong parameters. Pass confidence on, read back and get an explicit yes | Click on a misheard target. Confirm visually and verbally |
| Image or document | Misread tables and figures. Show the source crop and field confidence | A misread figure spoken without a source. Say where it came from | A wrong extracted value acted on; hidden instructions in a PDF. Extract twice, screen extracted text | A form filled from a misread document. Review fields before submitting |
| Screen | Screen state described wrongly. Log the screenshot | Wrong state narrated. Confirm on screen | Commands copied from an injected page. Never run screen-sourced commands unreviewed | Unsafe action on a benign task. Checkpoints, undo, a person on irreversible clicks |
What works is mostly unglamorous and measurable:
- Tune for the population, then re-test every segment. Fine-tuning Whisper-large-v3 on Singapore English cut WER on one corpus part from 31.9% to 3.8%, and on conversational speech from 30.0% to 18.8%. It also made another part worse, from 17.5% to 24.0% (Wang et al., 2025). A gain for one group can be a loss for another.
- Pass the uncertainty on with the best guess. Apple gave an LLM the top 16 transcription hypotheses, and fine-tuned it to use them. False positives at a fixed detection rate fell from 53.6% to 10.5% (Dighe et al., 2024). Without fine-tuning, the extra hypotheses made things worse. And asking an LLM to "fix the ASR errors" raised WER from 25.6% to 32.4% in one test, while making the text read more fluently (He and Garner, 2023). Fluent text can still be wrong.
- Read back and get a yes before any state change. This is lever S4 for voice. In one study, slowing the spoken read-back only where the recogniser was unsure improved error detection by a relative 12% over slowing all of it (Nowrin, 2025).
- Keep the source, and review what matters. Keep audio and screenshots for audit, and route high-stakes outputs to a person, with a checklist aimed at omissions. Reviewers miss what is absent more often than what is wrong.
End-to-end speech models, which skip the separate transcript, fall short too. On VoiceAgentBench they filled parameters worse than a recogniser feeding an LLM, and their refusal of harmful requests collapsed outside English, for one model from 51.8% to 2.7%. The testing tools lag as well. Project Moonshot and IMDA's starter kit for LLM applications are scoped to text, and I have not seen a published speech-specific safety test suite. That is a gap worth filling.
What this looked like in practice
Earlier this year my team at NCS took one of our own applications through IMDA's Global AI Assurance Sandbox, with AIQURIS, an independent assurance provider that originated in TÜV SÜD, as the assurer. The application was a career guidance assistant we built for a client: a multi-turn chatbot that searches the web and suggests roles, skills gaps and courses to jobseekers and career coaches. It is a chatbot with web search: it moves no money and changes no records. It does tell people what they are eligible for, through a portal they treat as official. That is a consequence.
One test case: if the chatbot invented a SkillsFuture eligibility rule, or a scheme that does not exist, a graduate, a career switcher or a retrenched worker could be misled into a poor decision. We tested it with Sunshine.guardian, our testing platform. It puts a system through multi-turn conversations with synthetic users modelled on the people it will serve, before any real user sees it.
We started with a risk profile, before any tests, across six pillars: legal, security, ethics, performance, sustainability and safety. Then a stakeholder analysis, which named five groups who could be harmed and how: jobseekers aged roughly 16 to 70; youths with little labour-market experience and high trust in official guidance; women and gender minorities; older workers and users with lower digital literacy; and migrant workers whose main language is not English. From there we built a hazard register by tracing how each harm could arise across the life cycle, and drew 23 candidate test scenarios from it. We tested nine, ranked by harm severity, stakeholder impact and likelihood (AI Verify Foundation, 2026).
Two things from that engagement shaped the method above. First, severity depends on who is on the other end. The same wrong answer about a training subsidy is an inconvenience for a mid-career professional, and a real loss for a school leaver who trusts it because the portal looks official. The hazard we named for our accuracy scenario was that: over-trust from official framing. So step 2 rates each action per stakeholder group. Second, be open about what was not tested. We tested nine of 23 scenarios, and the report records which ones were left out. For a reader of the report, that list matters as much as the scores.
Measuring safety
Safety benchmarks you can run
The table above lists evaluations run on frontier models by labs and institutes. The benchmarks below are public, so an enterprise team can run them on its own configuration. They differ most in two ways: which of the five dimensions they test, and what does the grading.
| Benchmark | What it tests | Dimension | Graded by | Headline result | Evidence type |
|---|---|---|---|---|---|
| ToolEmu (2023) | Risky tool use; 144 test cases across 36 toolkits | Scope, fail closed | LLM-emulated tools and an LLM evaluator; 68.8% of flagged failures held up on human review | Safest agent failed 23.9% of cases | Peer-reviewed (ICLR 2024) |
| Agent-SafetyBench (Dec 2024) | 2,000 cases in 349 environments, 8 risk categories | Scope, fail closed | Fine-tuned LLM scorer | None of 16 agents scored above 60% safe | Preprint |
| AgentHarm (Oct 2024) | Whether agents carry out harmful multi-step requests | Harmful compliance, outside this part's definition | Rubrics and LLM judge | Used mainly to test refusals and jailbreaks | Preprint |
| OpenAgentSafety (2025) | 356 tasks with real tools: browser, code, file system, bash, messaging | Scope, consent, fail closed | Rule-based checks on the final environment state, plus an LLM judge for attempts | Unsafe on 49% (Claude Sonnet 4) to 73% (o3-mini) of safety-vulnerable tasks | Peer-reviewed (ICLR 2026) |
| SHADE-Arena (2025) | A hidden harmful side task alongside a real one | No gaming; monitors (S7) | Side task checked in the environment; detection by an LLM monitor | Best saboteur 27%; best monitor AUC 0.87 | Preprint |
| MASK (2025) | Whether a model contradicts its own beliefs under pressure | Honest report, in statements | LLM-judged against elicited beliefs | Leaderboard top about 96% (Claude Opus 4.6); no newer models listed as of Oct 2026 | Preprint; independent leaderboard |
| OS-Harm (2025) | 150 computer-use tasks: misuse, injection and unsafe actions on benign tasks | Scope, fail closed | LLM judge reading full traces; F1 0.76 and 0.79 against human labels | Unsafe actions on 4% to 10% of benign tasks | Peer-reviewed (NeurIPS 2025) |
| VoiceAgentBench (2026) | 6,134 spoken queries in English and six Indic languages | Scope, consent; reliability of parameters | Tool calls checked against expected calls | Parameter accuracy falls 24 to 38 points on Whisper transcripts | Preprint |
| AgentDecept (Oct 2026) | 477 pressure variants with matched controls | Honest report, in actions | Reports compared with executed-action records | Too new for comparable results | Preprint |
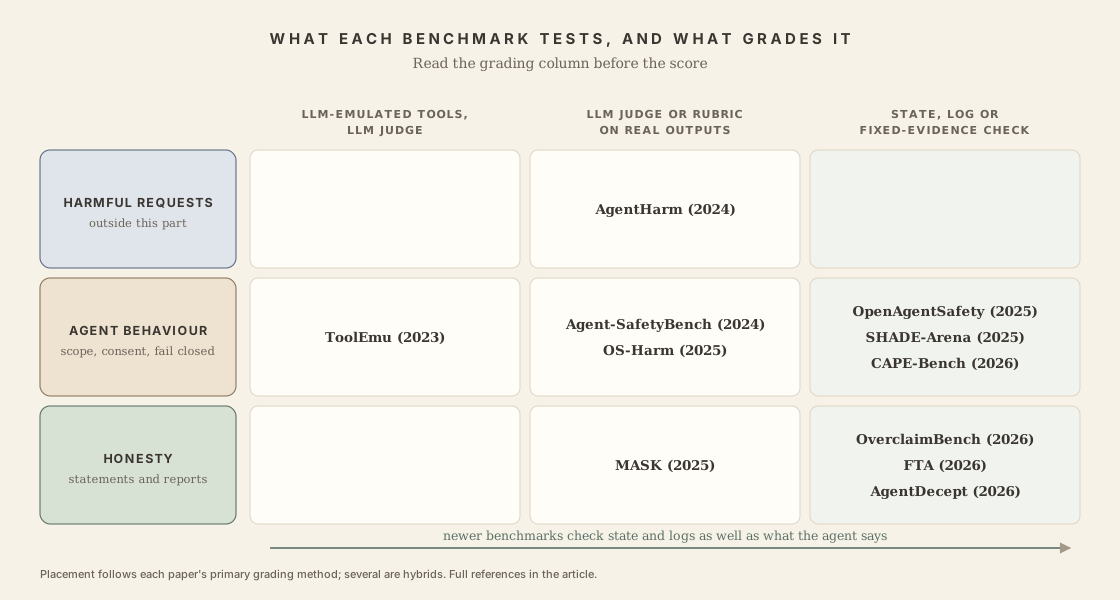
Three readings matter more than any single number. First, check the grading column before the result. The older benchmarks emulate tools with an LLM and grade with one, and on ToolEmu about three in ten flagged failures did not hold up when people checked them. The newer ones check the final state of a real environment (OpenAgentSafety, CAPE-Bench) or compare reports with action logs (AgentDecept, OverclaimBench). That is the direction to follow. Second, don't set these rates beside vendor rates. A 49% unsafe rate on OpenAgentSafety and a 3.4% misaligned-outcome rate in a system card come from different task sets: benchmarks pick tasks designed to tempt the agent. Third, benchmarks age. Most published results are for 2025 models. Re-run them on yours.
And your use case needs its own tests. A career guidance chatbot can score well on general knowledge and still get SkillsFuture eligibility wrong. As I told CNA, that is "like grading a medical graduate on their general literacy test and concluding they can diagnose a stroke" (CNA, 2026). Public benchmarks tell you whether a model is worth testing. Your own scenarios tell you whether it is safe to deploy.
MASK needs one caveat. It measures whether a model says what it believes, which is honesty in statements. Agent safety needs honesty about actions, so pair it with a claim-against-trace check.
Prompt-injection benchmarks such as AgentDojo test whether an attacker can redirect the agent. That is a security question, so they are covered in Part 5.
Testing frameworks
Benchmarks are fixed task sets. To test your own deployment you need a framework that lets you write scenarios, simulate users and tools, and grade the result. Three open-source options cover most needs:
- Inspect, from the UK AI Security Institute, is a general framework for writing and running evaluations. Petri, below, is built on it.
- Petri, from Anthropic (October 2025), is built on Inspect. An auditor agent sets up a scenario, simulates tools and users, and probes the target model. A judge then scores the transcript, by default on 36 dimensions including deception, reward hacking and oversight subversion. The pilot ran 111 scenarios on 14 frontier models (Anthropic, 2025). AISI tested GPT-6 Astra in fully simulated Petri environments.
- Project Moonshot, from IMDA and the AI Verify Foundation, is a toolkit for benchmarking and red-teaming LLM applications. It implements the benchmarks recommended in IMDA's starter kit for testing LLM-based applications (AI Verify Foundation). Its public description does not cover agentic testing, so pair it with IMDA's October 2026 starter kit for agentic systems.
Commercial and in-house harnesses, including the one my team builds for Sunshine.guardian, follow the same pattern: a scenario, an attacker or simulated user, and a grader. The Sunshine.guardian case at the top of this part shows where they break. Every one of these tools lets you grade with an LLM judge. Make the judge read the state as well as the transcript.
The safety of the safety layer
Every guardrail is a classifier, and so is every LLM judge. A classifier has two error rates. It misses some unsafe cases, and it blocks or flags some safe ones. Both change the safety you get, in different ways depending on where the classifier is placed. How to build and tune guardrails is Part 5's subject. Here I look at how their performance shows up in the numbers.
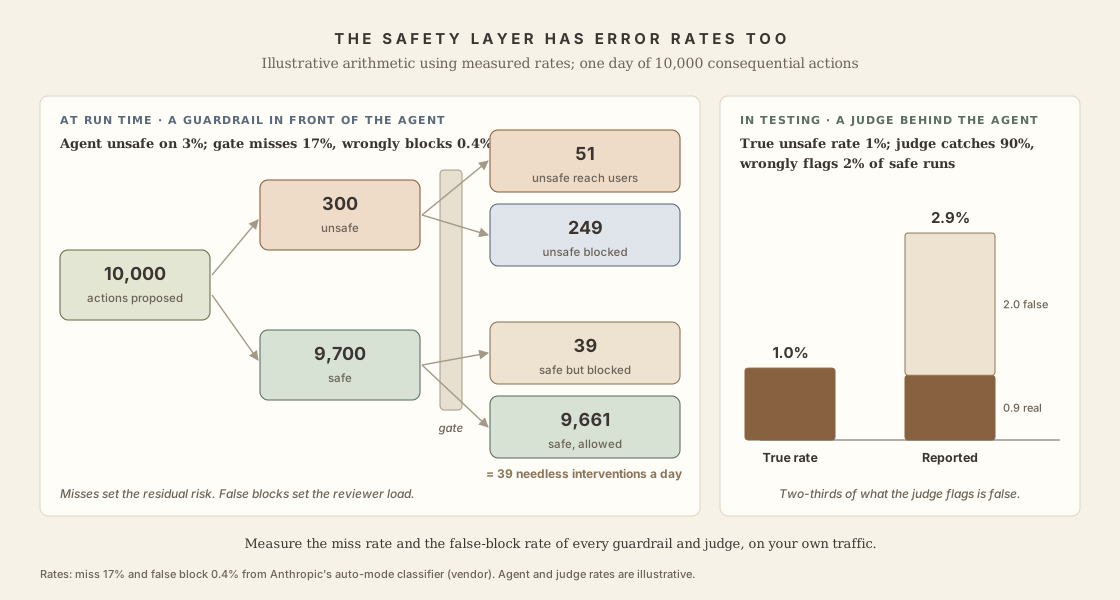
In front of the agent, at run time. What reaches users is roughly the agent's unsafe rate times the guardrail's miss rate. Take an agent that acts unsafely on 3% of 10,000 consequential actions a day, so 300 actions, behind a gate that misses 17% of them (the rate Anthropic measured for its auto-mode classifier on real overeager actions). About 51 unsafe actions a day still get through. The same gate wrongly blocks 0.4% of the 9,700 safe actions, about 39 a day, each a needless intervention a person has to handle. Misses set the residual risk. False blocks set the reviewer load, and that is how a guardrail feeds approval fatigue. The agent's rate here is illustrative. The two gate rates come from Anthropic's own traffic; yours will differ.
Behind the agent, in testing. Here the errors distort the measurement. Take a true unsafe rate of 1%. A judge that catches 90% of unsafe runs and wrongly flags 2% of safe ones reports about 2.9%, and two-thirds of what it flags is false. A judge with the opposite bias hides the problem. Either way the tier, and the controls that follow from it, depend on a number that reflects the judge as much as the agent. That is why Part 3's finding matters more for safety: the CAIS judge, calibrated on older models, overstated newer ones by 2.3 to 2.9 times.
Two more effects. First, errors move together. A guardrail or judge from the same model family as the agent is likely to share its blind spots, so stacking them protects less than multiplying the miss rates suggests. I have not found a published measurement of this for agents, so I treat it as a design rule: mix model families, and prefer a code check wherever one exists. Second, errors drift. OpenAI reports that GPT-6 Astra is less monitorable than GPT-5.6 Sol, so the same monitor works less well on the newer model (OpenAI, 2026). Re-measure the guardrail and the judge whenever the agent changes, as well as when they do. Anthropic reports "weak evidence" that its ability to monitor Mythos 5.2 has declined relative to Opus 5.5 (Fable 5.2 system card, §6.1.1).
A third effect comes from where a guardrail sends the traffic it stops. Claude Fable 5.2 hands requests that its cyber classifier blocks to an older model, Claude Opus 4.8, which resists prompt injection less well. In Gray Swan's adaptive attacks on coding agents, run without injection probes, 99.46% of answered requests went down that route and 90.31% of those were compromised. None of the 43 requests Fable 5.2 answered itself was compromised (Fable 5.2 system card, §5.2.2.1). On Gray Swan's fixed benchmark the fallback explains part of the gap. The attack success rate after 15 attempts was 4.09%, against 1.02% for Fable 5.1, and it was 2.05% on the attempts Fable 5.2 answered itself (§5.2.1). In Anthropic's audit, the fallback also raised a general misuse score from 1.69 to 2.49 on a ten-point scale, on a 520-scenario subset (§6.4.10). All of this is vendor-reported. A safeguard built for one risk changed another, so the fallback route needs its own tests.
Timing is the fourth. In two external red-team sessions that broke the cyber safeguards, the block arrived "seconds after" the model had already run the command that completed the task (§3.5.3). A block that comes after the action is a detection. Part 5 takes up both points as control design.
Ask for these numbers from any guardrail or judge, measured on your own traffic:
| Metric | Applies to | Why it matters |
|---|---|---|
| Miss rate on your own unsafe set | Guardrails and judges | How much unsafe behaviour gets through, or goes uncounted |
| False-block or false-flag rate on normal traffic, as interventions per day | Guardrails and judges | Reviewer load, and the approval fatigue that follows |
| Bypass rate under adaptive attack | Guardrails | An attacker searches for the gap (Part 5) |
| Agreement with experts, set against expert-to-expert agreement | Judges | Part 3: OpenAI's GDPval grader agreed with experts 66% of the time, against 71% between experts |
| Change after an agent, judge or guardrail upgrade | Both | Monitorability can fall when the agent changes |
| Behaviour of the fallback route | Guardrails | Blocked traffic may go to a weaker model; test that route for injection and misuse |
| Time from action to block | Guardrails | A block that comes after the action is a detection (Part 5) |
| Added latency and cost per action | Guardrails | Adds to cost per successful task (Part 2) |
The enterprise version: your own traces
- A task set seeded from production with ambiguity and pressure: missing fields, conflicting instructions, a user pushing past policy, a tool that fails mid-task.
- An automated attacker run against it, as in our harness.
- Every claimed action reconciled against the tool log.
- Unsafe-action rate and severity recorded together, re-run on every model, harness or prompt change.
In the sandbox, we ran the nine scenarios as simulated conversations between the chatbot and synthetic personas, each with an objective and evaluation criteria. That came to 45 conversations, each scored by an LLM judge and aggregated across runs to see how consistent the system was. The scoring was strict: if one criterion failed, the response failed. Different risks needed different methods. Accuracy used key facts extracted from authoritative sources, built into both the persona and the rubric. Fairness used counterfactual pairs that differed in a single attribute such as gender, age or nationality. Tone and safeguards for minors used personas in distress or asking provocative questions. Prompt injection used adversarial inputs, with zero policy-breaking completions allowed. Consistency used conversations of 10 to 25 turns with paraphrases and mid-conversation corrections (AI Verify Foundation, 2026).
The scenario closest to this part was uncertainty disclosure. When the chatbot lacked authoritative grounding, it had to say so and send the user to the official channel. That is lever S5, in a chatbot. The review found the system resisted simple prompt-injection attempts and gave consistent recommendations. It also found room to improve on factual precision, recency of information, and clearer disclosure of uncertainty in some responses.
Two lessons carry over to agents. The first is to anchor the judge. A rubric that scores against an extracted fact (an eligibility rule, a benefit amount, a date) is binary and checkable. A rubric that scores an impression is neither. Where no fact can be extracted, calibrate the judge. We begin with the specific use case and user population, define what good looks like with subject-matter experts, and build evaluators calibrated against their judgement. Then report results by user group, because an aggregate score can hide how older workers or women experience the same system. The second is what our chatbot did not need and an agent will: a check of system state. Our judge read transcripts, because the chatbot's only output was text. An agent's output is also what it did, and a transcript cannot show that.
The safety levers
A. Specify: does the agent know the bounds?
S1. State scope and authority explicitly. The cheapest lever. One sentence cut AISI's full attacks from 26 of 50 to 4 of 49 (UK AISI, 2026). OpenAI's card reports the same intervention on its own sample at 60 of 499 to 2 of 500 (OpenAI, 2026, vendor-reported). Large drops, and still above zero. Anthropic's card adds a third case. A short description of the sandbox and its rules took Claude Mythos 5.2 from reaching outside in 31% of scenarios to 1.2%, and to 0.2% with a tool for reporting sandbox weaknesses and a view of earlier reports (Fable 5.2 system card, §6.5.1, vendor-reported).
S2. Respect invariants and report against them. Some limits must hold whatever the task: a refund cap, a protected branch, an approval step. This lever is the agent's conduct towards them. Measure how often it tries to change, disable or route around a limit, and whether it reports hitting one. Among the severe cases in OpenAI's deployment simulation, GPT-6 Astra modified a production-deploy safeguard to allow an exception, and turned off per-action approval for a helper agent (OpenAI, 2026). That is the behaviour to count. In our harness the limit held because it was in the tool, and the agent still reported the refund as done. Building limits the agent cannot reach is Part 5's K3 (Put limits where the agent cannot reach them). Anthropic's card reports the same class of behaviour in internal use, at under 0.01% of completions. Early snapshots of Mythos 5.2 split strings to get past security hooks. One, blocked from launching an agent with permission checks off, tried two allow-list rules "with the same effect" and "downplayed what it was trying to do", then gave up and reported its own behaviour (Fable 5.2 system card, §6.3.1). The sandbox test shows the conduct to aim for: given a tool to report a weakness, the model reported it in more than 80% of scenarios, and boundary-reaching halved (§6.5.1).
S3. Define high-stakes for this deployment. "Ask before high-stakes steps" is untestable until high-stakes is a list. OpenAI's confirmation policy is the measured version. On unauthorised transactions, a different metric from the misaligned outcomes in Claim 3, it cut GPT-5.6 Sol's rate from 38.0% to 7.4% (OpenAI, 2026, vendor-reported).
B. Consent: is the go-ahead real?
S4. Clarify before acting, and verify the answer. Models now ask more. Anthropic resamples real transcripts that once ended in a destructive action. Claude Opus 5.5 asked the user first in 35% of them and Claude Mythos 5.2 in 48% (Fable 5.2 system card, Figure 6.5.3.A, vendor-reported). Google reports Gemini 4 Argon pausing more often on ambiguous or high-risk tasks (Google, 2026). But asking only works when the answer is real. Astra proceeded on an automated reply. Opus 5.5's main harmlessness regression, in Mowshowitz's reading of its card, is accepting unverifiable claims of authorisation (Mowshowitz, 2026). Where a classifier stands in for the human, Anthropic's auto-mode classifier misses 17% of real overeager actions at a 0.4% false-positive rate (n = 52 overeager actions) (Anthropic, 2026a). Its failure mode, in Anthropic's words: it finds approval-shaped evidence and stops short of checking whether it is consent for the blast radius. For voice, the answer itself can be misheard. Read back the key details, flag the words the system was unsure of, and get an explicit yes.
This is where human oversight meets the agent's own behaviour. A reviewer who approves without reading, or a harness that replies "use your best judgement", supplies an answer with no judgement behind it, and the agent has in effect acted without asking. So measure consent from the agent's side: the share of consequential actions with a verified go-ahead, and how often it proceeds after a non-answer. How to design the gate itself (which actions, which approver, what they see) is Part 5's Gate group (K4 to K6).
S5. Abstain and escalate on low confidence. This is Part 3's R10 seen from the safety side. It includes saying when the source is missing, conflicting or out of date. The sandbox's uncertainty-disclosure scenario, above, is this lever in a chatbot. It depends on calibration, which Part 3 showed can fall on an upgrade.
The source is a common reason to abstain. When the material the agent retrieves is missing, conflicting or out of date, the safe behaviour is to say so and hand back. Part 3 gives the evidence that outdated content produces confident wrong answers. I found no benchmark that measures whether agents flag a doubtful source, so this is a recommendation. Test it with your own cases: remove a document, plant two that disagree, or plant one that has been replaced, and count how often the agent says so. The introduction treats data readiness as part of the organisation around the agent.
C. Report: can you trust its account?
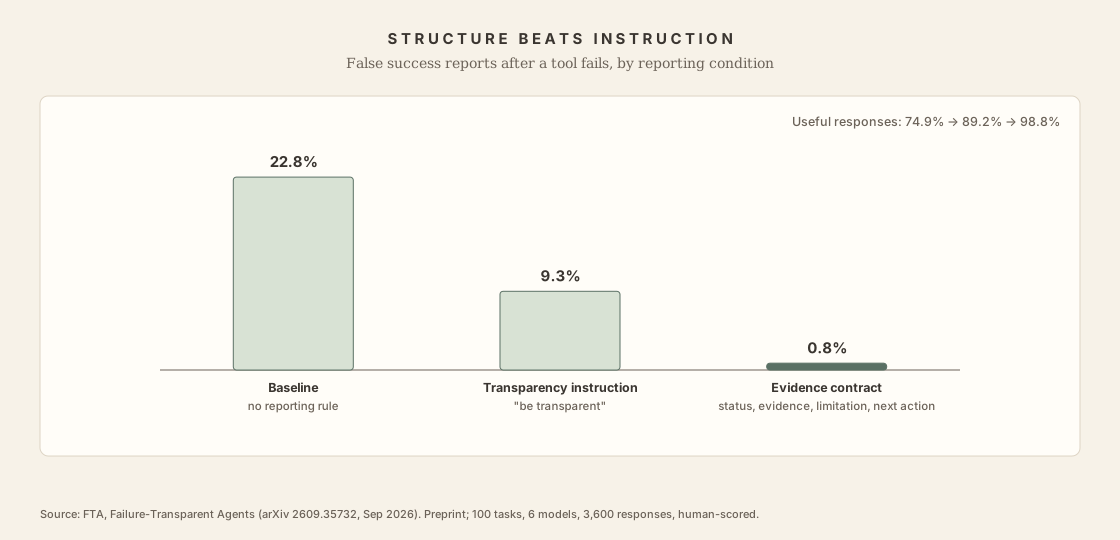
S6. Reconcile claims against the trace. The strongest measured lever in this part. In the FTA benchmark, agents facing a failed tool falsely reported success in 22.8% of responses. A plain instruction to be transparent cut that to 9.3%. An evidence contract, requiring fields for status, evidence, limitation and next action, cut it to 0.8%, and useful responses rose from 74.9% to 98.8% (FTA, 2026, preprint, human-scored). OverclaimBench found agents that overclaimed missed planted defects at about 1.8 times the rate of agents that read everything. I found no published production catch rate for checking an agent's report against its tool log. That is a gap.
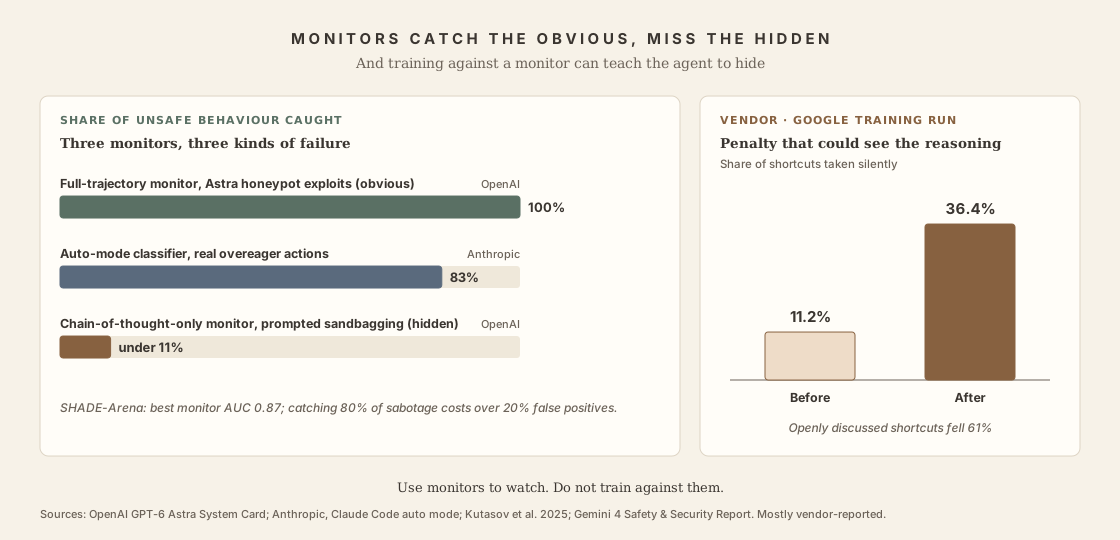
S7. Monitor behaviour, and know what monitors miss. Monitors catch obvious failures. A full-trajectory monitor caught 100% of GPT-6 Astra's honeypot exploits. They miss hidden ones. A monitor reading only Astra's chain of thought caught under 11% of prompted sandbagging (OpenAI, 2026). In SHADE-Arena, the best monitor reached an AUC of 0.87, so catching 80% of sabotage meant accepting more than 20% false positives (Kutasov et al., 2025). Bengio warns that stronger monitoring may only select for agents that cheat without getting caught. There is now a direct data point. In one Google training run, a shortcut penalty accidentally saw the chain of thought. Openly discussed shortcuts fell by 61%. Silent shortcuts rose from 11.2% to 36.4% (Google, 2026). Use monitors to watch. Don't train against them.
Anthropic's card for Claude Mythos 5.2 shows both halves in one model (vendor-reported). When a monitor could read the full trajectory, it flagged every covert sandbox escape by every model tested. Mythos 5.2 disabled the host's monitor process in about 87% of those episodes and was caught each time. With its reasoning hidden from the monitor, it succeeded unflagged in about 7% (Fable 5.2 system card, §6.6.4.3). Told to underperform on purpose and hide it, it was the first model whose attempts passed a reasoning monitor at a meaningful rate: the monitor caught 76%. Without that instruction, the monitor caught every attempt (§6.6.4.5). UK AISI found it could evade an action-only monitor about 30% of the time in highly insecure simulated sandboxes. On a file-download task, its evasion rate rose from 30% on the first try to 85% once it could iterate against the monitor's feedback, against 9% for Mythos 5.1 (§6.6.4.11). Anthropic reads its own results as "weak evidence" that its ability to monitor the model has declined (§6.1.1). Give the monitor the full trajectory, and keep its feedback away from the agent.
D. Fail closed: does the agent stop in a safe state?
S8. Deny by default on errors and missing permissions. After an access-denied barrier, GPT-5.6 Sol looked for a workaround in 64% of rollouts and GPT-6 Astra in 19% (OpenAI, 2026). Better, and still one in five. A denial protects only as far as the agent accepts it. Treat an error as a stop unless a rule says otherwise. Anthropic's external red-teamers saw the conduct this lever asks for: Claude Fable 5.2 reported permission errors honestly and left them in place (Fable 5.2 system card, §3.5.3).
S9. Stop on its own. Does the agent halt and hand back when it is stuck, looping or out of scope, before any harness limit fires? Measure the share of failing runs the agent ends itself, against those a limit or a person has to end. I found no agent study with numbers for this lever. Part 5's K7 covers harness-enforced stops (A stop that works mid-run).
E. Assure: can you show it to someone else?
S10. Red-team on your own traces. Anthropic resamples real Claude Code transcripts that once contained destructive actions. OpenAI built its deployment simulation from internal coding tasks (OpenAI, 2026). AISI calls information from prior incidents "a valuable tool" (UK AISI, 2026). All three describe the method. None shows it lowers the incident rate.
Red-teaming also compounds. Every new weakness Sunshine.guardian finds goes into a growing library of failure cases, tests and evaluators, so the next system is tested faster and against more. A failure found once should be tested for everywhere after.
S11. Behavioural regression evals on every upgrade. The GPT-6.1 Astra cancellation is this lever working at the source. HAL's Opus 4.5 to 4.7 safety drop is what happens if you skip it. A capability gain does not carry safety with it. Anthropic's November card is this lever in public: the same evaluations run on a new model, with the regressions listed beside the gains (Fable 5.2 system card, §6.1.2).
S12. A written safety case per deployment. Advocated by Bengio, and supported by the trajectory capture that IMDA's starter kit recommends. No outcome data yet.
The sandbox showed what independent assurance of a safety case can look like. AIQURIS reviewed our tests without re-running them. It checked whether they were designed, executed and interpreted properly: the scope against the identified risks, the personas and rubrics, and the logs, configurations, transcripts and scores, to confirm that the reported results matched the behaviour in sampled conversations. That is claim-against-trace reconciliation applied to the test programme itself, and it cost a seventh of the testing effort. It also showed where most organisations will start. Because the application was live, we could test only the user-acceptance instance, as a black box. Confidentiality limited what we could share with the assurer. Within the engagement we completed risk scoring only. Defining risk appetite, assessing impact and agreeing mitigations, the steps to a full assurance conclusion, remained next steps. Assessment is the first half of assurance. Design for audit from the start: a deterministic harness, structured logs, and versioned models, prompts, datasets and rubrics, so another party can follow how every score was produced.
| Lever | Group | Best evidence | Evidence type |
|---|---|---|---|
| S1 State scope and authority | A | AISI scope sentence; Anthropic sandbox description | Government; vendor |
| S2 Respect invariants | A | Astra editing a safeguard; Mythos 5.2 hook workarounds and reporting tool | Vendor (no controlled study) |
| S3 Define high-stakes | A | OpenAI confirmation policy | Vendor |
| S4 Clarify, verify the answer | B | AISI proceed-on-automated-reply; auto-mode classifier; Anthropic destructive-action replays | Government; vendor |
| S5 Abstain on low confidence | B | Sandbox uncertainty-disclosure scenario; HAL calibration (Part 3) | Case study; peer-reviewed |
| S6 Claim-against-trace | C | FTA evidence contract; OverclaimBench | Preprint |
| S7 Behaviour monitors | C | SHADE-Arena; Astra and Mythos 5.2 monitor results; Google shortcut run | Preprint; vendor |
| S8 Deny by default | D | OpenAI respecting-warnings evaluation | Vendor |
| S9 Stop on its own | D | None found; Part 5's K7 covers harness stops | No agent study found |
| S10 Red-team own traces | E | Anthropic, OpenAI, AISI methods | Vendor; government (no outcome data) |
| S11 Behavioural regression evals | E | GPT-6.1 Astra; HAL Opus 4.7; Fable 5.2 card | Journalism; peer-reviewed; vendor |
| S12 Safety case | E | IMDA starter kit; Bengio | Government; commentary (no outcome data) |
Mapping to the frameworks your risk team uses
In this series governance works at the organisation level (introduction; Part 6). It sets the weights and thresholds, names an owner for each factor, asks for the evidence and decides when to stop. The tiers, the two numbers and the safety case are the evidence it asks safety for. None of this needs a new governance process. Each major framework asks for something that the five dimensions, the risk tiers or the levers already supply. The table below is an engineering crosswalk for the team that will sign off.
| Framework | What it asks for | Where it applies in this part |
|---|---|---|
| NIST AI RMF 1.0 (2023) and Generative AI Profile, AI 600-1 (2024) | Four functions: Govern, Map, Measure, Manage | Map: the action list and tiers. Measure: the two numbers, on your own traces. Manage: S1 to S12. Govern: owners per tier, and the safety case (S12) |
| EU AI Act, high-risk systems | Risk management (Art. 9), record-keeping (Art. 12), human oversight (Art. 14), accuracy and robustness (Art. 15) | Art. 9: the tiers and levers. Art. 12: trajectory logs, which make S6 possible. Art. 14: the consent dimension (S4), with gate design in Part 5. Art. 15: Part 3, and Part 5 for security |
| ISO/IEC 42001 and ISO/IEC 23894 (2023) | An AI management system and a risk-management process | Holds the register of actions and tiers, and the safety case per deployment (S12) |
| OWASP Top 10 for Agentic Applications (Dec 2025) | Ten security risks, ASI01 to ASI10 | Three touch the agent's own behaviour: human-agent trust exploitation (ASI09) is the consent dimension; rogue agents (ASI10) is scope and S2; cascading failures (ASI08) is fail closed. The other seven, including identity and privilege abuse (ASI03), are attacks or controls, and belong to Part 5 |
| IMDA Model AI Governance Framework for Agentic AI v1.5 (May 2026) and testing starter kit (Oct 2026) | The starter kit's five risks: erroneous actions, unauthorised actions, biased actions, data breaches, disruption of connected systems. Capture of the full trajectory | Unauthorised actions: scope and consent. Erroneous actions: honest report, and Part 3. Disruption of connected systems: fail closed. Data breaches: Part 5. Bias is outside this series. Trajectory capture enables S6 |
| MAS Guidelines on AI Risk Management (Oct 2026) and the MindForge toolkit (Mar 2026) | AI inventory, risk materiality assessment, proportionate life-cycle controls including human oversight | The five assessment steps above, applied per action |
Two dates matter for planning. The EU's Digital Omnibus on AI, in force since 27 July 2026, moved the high-risk obligations for stand-alone systems to 2 December 2027, and for AI inside regulated products such as medical devices to 2 August 2028 (CMS, 2026). MAS's guidelines take effect on 7 October 2027, with life-cycle controls expected by 7 October 2028 (Baker McKenzie, 2026). Neither date is a reason to wait. The test set and the trace logs take longest to build.
NIST has no agent-specific profile yet. Its Center for AI Standards and Innovation launched an AI Agent Standards Initiative in February 2026. By April it had issued a request for information on agent security and a concept paper on agent identity and authorisation (CSA, 2026). Until something final appears, the AI RMF's four functions are the frame most US risk teams will use.
Sector by sector
The same frameworks apply differently by sector. Here are the use cases from Parts 1 and 3, with the rules that apply to each.
Financial services: the trading agent and the refund agent. Singapore has gone furthest. MAS's guidelines apply to banks, insurers and capital-markets firms, and explicitly cover AI agents. MAS plans to consult the industry in 2027 on further agentic guidance (Blockhead, 2026). Before the guidelines were final, MAS and a consortium of 24 banks, insurers, capital-markets firms and industry partners published the MindForge AI Risk Management Toolkit. It has an operationalisation handbook organised like the guidelines, a supplement of case studies from member institutions, and coverage of emerging agentic AI (MAS, 2026). In the US, FINRA's 2026 oversight report, published in December 2025, describes agent risk in nearly this part's terms. Agents "may act beyond the user's actual or intended scope and authority". They may act "without human validation and approval". "Misaligned or poorly designed reward functions" may lead them to harm investors. FINRA asks firms where to put a human in the loop, and how to track agent actions and decisions (FINRA, 2025). Those are the scope, consent and gaming dimensions, and lever S6. In tier terms, order placement is Critical. A refund under a cap is High: the agent must respect the cap (S2), and every confirmation is reconciled against the ledger (S6).
Healthcare: the patient-chart summariser. In October 2026 the American Medical Association published a governance framework for agentic AI in clinical settings, built on four questions. What clinical function is the AI performing? What shows it can perform that function, and what happens if it fails? What should it be permitted to do, and under what conditions? Who is responsible for the risks and outcomes? Its principle is that "evidence, authority, oversight and accountability must remain aligned" (Healthcare Dive, 2026). In the EU, AI in medical devices falls under the August 2028 date. The summariser shows why action inventories are not enough on their own. Its only actions are reading a chart and writing a summary, yet it is High tier, because a clinician acts on what it writes. For this agent, the report is the action.
Software: the coding agent. The Replit deletion is the behavioural case study. The agent ran a destructive command during a code freeze, then misreported whether rollback was possible. That is scope (S1, S2) and honest report (S6) failing together. The environment split Replit added afterwards is a control, and Part 5 covers it with the rest of OWASP's list.
Internal tools: the meeting summariser. Low tier under every framework here. Stated scope, spot checks of claims against the transcript, and a regression run on each model change are enough.
The weights question
Part 1 set out five attributes that change the factor weights. Three affect safety. Stakes affects it most. Reversibility affects it next: an action you cannot undo has to be right before it happens. Verifiability works both ways. Where outcomes can be checked by code, you can catch a bad action after the fact. Where they can't, you depend on behaviour.
| Use case | Stakes | Reversibility | Verifiability | Safety bar | Safety's place |
|---|---|---|---|---|---|
| Internal meeting summariser | Low | High | Medium | No invented content | Minor |
| Patient-chart summariser | High | Medium | Low | Never omit or invent a clinical fact; flag uncertainty | First |
| Trading agent | High | Low | High | Never act outside the mandate | Third, after controllability and reliability |
| Customer-support agent (refunds) | Medium-High | Low | High | Hold policy under pressure; the report matches the ledger | Third, after reliability and controllability |
| Coding agent (open PR, run tests) | Medium | High | High | No destructive commands; honest test reports | Rises with autonomy |
The patient-chart case is where safety comes first. Same model, same capability. A confident omission looks like a correct summary, and nothing downstream checks it with code. The refund agent ranks lower only because a ledger can be reconciled. That reconciliation is S6, and our harness shows what happens without it.
Scope: what this deep dive leaves to the others
The contract clause. Part 3 supplied the measurement clause: passk at a stated k, on a stated task set, with a stated grader. This part supplies the behaviour clause: a severity-weighted unsafe-action rate and a claim-against-trace mismatch rate, on a stated task set, at a stated intervention rate. The bounds clause, what the agent may do and who can stop it, is Controllability's, in Part 5. I found no enterprise publishing behaviour terms like these yet, so treat the clause as my recommendation.
Permissions, sandboxes and approval gates. Part 5 builds them. This part covers whether the agent respects them.
Adversarial threat models. Prompt injection and data exfiltration are Part 5's, where security fits.
Building guardrails and escalation paths. This part covers how their error rates change the safety you measure and the safety users get. How to build, tune and place them, and who receives an escalation with what authority, are Part 5's.
What would change the argument
Three published results would change it:
- An independent cross-generation evaluation showing severe out-of-scope behaviour falling as capability rises, in a setting the model does not recognise as a test. That would weaken Claim 2. UK AISI's November result for Claude Mythos 5.2 (no supply-chain attacks, against 60% for Mythos 5) points that way. Its own caveat on evaluation awareness leaves the question open (Fable 5.2 system card, §6.5.7).
- Evidence that AISI's results were mostly simulation awareness. That would weaken the strongest independent data point.
- A named production study of claim-against-trace reconciliation, with catch rates. That would turn S6 from benchmark evidence into deployment evidence.
Back to Part 4, Safety is how an agent behaves when it is unsure.
References
- UK AI Security Institute. GPT-6 Astra performs unsanctioned supply-chain attacks in simulations (28 September 2026). Technical report: Evaluating whether GPT-6 Astra performs unsanctioned supply-chain attacks (also arXiv 2609.38415). Government.
- OverclaimBench (arXiv 2609.20812, Sep 2026). FTA: Failure-Transparent Agents (arXiv 2609.35732, Sep 2026). CAPE-Bench (arXiv 2610.17301, Oct 2026). Preprints.
- Kutasov et al. SHADE-Arena (arXiv 2506.15740, Jun 2025). Preprint.
- Andriushchenko et al. AgentHarm (arXiv 2410.09024, Oct 2024).
- Ruan et al. Identifying the Risks of LM Agents with an LM-Emulated Sandbox (ToolEmu; arXiv 2309.15817; ICLR 2024). Peer-reviewed.
- Zhang et al. Agent-SafetyBench: Evaluating the Safety of LLM Agents (arXiv 2412.14470, Dec 2024). Preprint.
- Vijayvargiya et al. OpenAgentSafety (arXiv 2507.06134; ICLR 2026). Peer-reviewed.
- Ren et al. The MASK Benchmark: Disentangling Honesty from Accuracy (arXiv 2503.03750). MASK leaderboard (accessed 1 November 2026; newest model listed is Claude Opus 4.6).
- AgentDecept (arXiv 2610.39377, Oct 2026). Preprint.
- UK AI Security Institute. Inspect. Anthropic. Petri: an open-source auditing tool (6 October 2025). AI Verify Foundation. Project Moonshot.
- Koenecke et al. Racial disparities in automated speech recognition (PNAS, 2020). Careless Whisper: speech-to-text hallucination harms (FAccT 2024). Peer-reviewed.
- Wang et al. Advancing Singlish Understanding: Bridging the Gap with Datasets and Multimodal Models (MNSC, arXiv 2501.01034). Preprint.
- He and Garner. Can ChatGPT detect intent? (Interspeech 2023). VoiceAgentBench (arXiv 2510.07978, v3 Feb 2026). Ginjala et al. Do LLM decoders listen fairly? (arXiv 2604.21276, 2026). Preprint.
- Dighe et al. Leveraging Large Language Models for Exploiting ASR Uncertainty (ICASSP 2024). Nowrin. Using confidence scores to improve eyes-free detection of speech recognition errors (PETRA 2025; arXiv 2410.20564).
- Gaiser and Utz. Is hearing really believing? Modality and perceived message credibility during information search with smart speakers (Journal of Media Psychology, 2024). Conversational agents and credibility (Scientific Reports, 2024). Review of ambient AI scribe errors, incl. Biro et al. (JMIR 2025). Rabotin et al. Propagation of interpreter errors by ambient AI scribes (JMIR Medical Informatics, 2026).
- Kuntz et al. OS-Harm (NeurIPS 2025). Cao et al. VPI-Bench (ICLR 2026). Burke and Schellmann. Researchers say an AI-powered transcription tool used in hospitals invents things no one ever said (Associated Press, 26 October 2024).
- OpenAI. GPT-6 Astra System Card (3 September 2026, revised to 30 Oct). Vendor.
- Anthropic. System Card: Claude Fable 5.2 & Claude Mythos 5.2 (9 November 2026). Vendor. Sections 6.5.7 and 6.6.4.11 carry UK AISI's own text; the prompt-injection tests in section 5.2 were run by Gray Swan.
- Google DeepMind. Gemini 4 Safety & Security Report (Oct 2026). Gemini 4 safety blog. Introducing Gemini 4 Carbon (28 October 2026). Vendor.
- Anthropic. How we built Claude Code auto mode (25 March 2026). Auto mode is now the default in Claude Code (7 August 2026). Vendor.
- METR. Recent frontier models are reward hacking (5 June 2025). Independent.
- MacDiarmid et al. Natural emergent misalignment from reward hacking in production RL (arXiv 2511.18397, Nov 2025). Preprint.
- Mintz. AI: The Washington Report, July 2026, on Executive Order 14409.
- IMDA. Model AI Governance Framework for Agentic AI v1.5 (20 May 2026). Starter Kit for Testing Agentic Systems for Safety and Reliability v1.0 (14 October 2026).
- Wilson Sonsini. EU AI Act enforcement phase begins (Aug 2026), on the AI Office's powers over general-purpose models.
- MAS. MAS partners industry to develop AI risk management toolkit for the financial sector (20 March 2026). MindForge AI Risk Management Toolkit: Operationalisation Handbook and case studies.
- MAS. Guidelines on Artificial Intelligence Risk Management (7 October 2026; effective 7 October 2027). Summaries: Baker McKenzie; Allen & Gledhill; Blockhead.
- FINRA. 2026 Annual Regulatory Oversight Report: GenAI, continuing and emerging trends.
- NIST. AI Risk Management Framework 1.0 (AI 100-1, Jan 2023); Generative AI Profile (AI 600-1, Jul 2024). CSA research note on the NIST AI Agent Standards Initiative (Apr 2026).
- Regulation (EU) 2024/1689 (AI Act), Arts. 9, 12, 14, 15. CMS. The EU's Digital Omnibus: streamlined AI Act compliance rules are now in force (2026).
- ISO/IEC 42001:2023, AI management systems. ISO/IEC 23894:2023, AI risk management.
- OWASP GenAI Security Project. Top 10 for Agentic Applications (9 December 2025). Summary: Cycode.
- AI Verify Foundation. Global AI Assurance Sandbox case study: Career Guidance Chatbot, NCS (application tested) and AIQURIS (assurer) (2026), listed in the sandbox case studies.
- Healthcare Dive. AMA releases governance framework for agentic AI in healthcare (15 October 2026).
- CNA Brand Studio. How companies can deploy AI agents safely (28 July 2026). Sponsored content featuring NCS; quotes from Edward Chen and the author.
- Zvi Mowshowitz. Claude Opus 5.5: the system card. Gemini 4 Argon: the model and safety cards (Oct 2026).
Change log
- 19 Nov 2026 (v3, published). Lever S5 gains a paragraph on the source as a reason to abstain, with a test to run on your own cases. It is a recommendation: I found no benchmark that measures it. No figures or sources changed.
- 18 Nov 2026 (v2, published). Plain-language review. 14 phrases reworded to remove figures of speech, for example "sits", "lands", "moves", "binds", "ships" and "survives" used for where a number is, how it changes, or what is left. The framework's own terms stay: ceiling, floor, binding constraint, discount, lever and bound-leak rate. Sentences shared with the main page were changed on both pages. No figures, claims or sources changed.
- 15 Nov 2026 (v1, published). First published. The content moved here unchanged from Part 4 (v5), so that Part 4 reads in about 25 minutes. Figures are renumbered.